 Login
Pig lung transplanted into a person in world first
26 August 2025 at 08:00
Nature, Published online: 26 August 2025; doi:10.1038/d41586-025-02708-2
Lungs are complex organs to transplant, but the surgery is a step towards clinical trials.


Nature, Published online: 26 August 2025; doi:10.1038/d41586-025-02708-2
Lungs are complex organs to transplant, but the surgery is a step towards clinical trials.
Nature Biotechnology, Published online: 25 August 2025; doi:10.1038/s41587-025-02777-8
An evaluation framework isolates perturbation-specific effects in perturbation datasets.
Br J Cancer. 2025 Aug 23. doi: 10.1038/s41416-025-03139-6. Online ahead of print.
ABSTRACT
Non-small cell lung cancer (NSCLC) represents a heterogeneous group of malignancies characterised by diverse histological and molecular features. Some NSCLCs, particularly adenocarcinomas, harbour genomic alterations in receptor tyrosine kinases or downstream RAS/RAF signalling pathways, which are targets of effective therapies. NSCLCs lacking actionable genomic alterations often benefit from immune checkpoint inhibitors, though only a minority of patients achieve long-term survival. These tumours often carry alterations in tumour suppressor genes like TP53, KEAP1, STK11, or NF1, for which pharmacological strategies are still under investigation. This review explores emerging therapeutic opportunities unveiled by multi-omics studies in NSCLCs without actionable genomic alterations. Proteogenomic approaches-integrating genomic, transcriptomic and proteomic data-enable a comprehensive understanding of NSCLC molecular landscapes and signalling network dysregulation, helping to identify distinct tumour subtypes and potential therapeutic targets. These tumours exhibit alterations in cell cycle regulation, DNA repair, immune signalling, epigenetic modulation and metabolic and redox pathways. Although therapies targeting tumour suppressor genes like p53 remain highly anticipated, extending our understanding of the broader molecular landscape in these tumours may reveal novel vulnerabilities and inform the development of novel drugs or combination strategies. This could further advance precision oncology for NSCLC.
PMID:40849356 | DOI:10.1038/s41416-025-03139-6
Cell Death Discovery, Published online: 23 August 2025; doi:10.1038/s41420-025-02705-4
Roles of lactylation in lipid metabolism and related diseases
Cell Rep. 2025 Aug 21;44(9):116191. doi: 10.1016/j.celrep.2025.116191. Online ahead of print.
ABSTRACT
Pancreatic ductal adenocarcinoma (PDAC) is a deadly disease, and new therapeutic strategies are urgently needed. Here, we conduct an integrative, genome-scale examination of genetic dependencies and cell surface targets using CRISPR-Cas screening and multi-omic data, including single-nucleus and spatial transcriptomic data from patient tumors. We systematically identify clinically tractable and biomarker-linked PDAC dependencies, including CDS2 as a synthetic lethal target in cancer cells expressing signatures of epithelial-to-mesenchymal transition. We examine biomarkers and co-dependencies of the KRAS oncogene, defining gene expression signatures of sensitivity and resistance associated with response to pharmacological inhibition of KRAS. mRNA and protein profiling reveal cell surface protein-encoding genes with robust expression in patient tumors and minimal expression in non-malignant tissues. Furthermore, we define intratumoral and interpatient heterogeneity of target gene expression and identify orthogonal targets that suggest combinatorial strategies. Collectively, this work identifies multiple targets that may inform therapeutic strategies for patients with PDAC.
PMID:40848256 | DOI:10.1016/j.celrep.2025.116191
Nat Commun. 2025 Aug 22;16(1):7827. doi: 10.1038/s41467-025-63146-2.
ABSTRACT
While dysregulation of polyamine metabolism is frequently observed in cancer, it is unknown how polyamines alter the tumor microenvironment (TME) and contribute to therapeutic resistance. Analysis of polyamines in the plasma of pancreatic cancer patients reveals that spermine levels are significantly elevated and correlate with poor prognosis. Using a multi-omics approach, we identify Serpinb9 as a vulnerability in spermine metabolism in pancreatic cancer. Serpinb9, a serine protease inhibitor, directly interacts with spermine synthase (SMS), impeding its lysosome-mediated degradation and thereby augmenting spermine production and secretion. Mechanistically, the accumulation of spermine in the TME alters the metabolic landscape of immune cells, promoting CD8+ T cell dysfunction and pro-tumor polarization of macrophages, thus creating an immunosuppressive microenvironment. Small peptides that disrupt the Serpinb9-SMS interaction significantly enhance the efficacy of immune checkpoint blockade therapy. Together, our findings suggest that targeting spermine metabolism is a promising strategy to improve pancreatic cancer immunotherapy.
PMID:40846845 | PMC:PMC12373741 | DOI:10.1038/s41467-025-63146-2
EClinicalMedicine. 2025 Aug 12;87:103406. doi: 10.1016/j.eclinm.2025.103406. eCollection 2025 Sep.
ABSTRACT
BACKGROUND: Recurrence risk after curative surgery for colorectal liver metastases (CRLM) remains high, underlining the need to identify prognostic markers enabling more individualised treatment approaches.
METHODS: In the MIRACLE, a prospective, observational biomarker study, a total of 188 patients with isolated, resectable CRLM without (neo)adjuvant chemotherapy were included between October 2015 and December 2021. Blood samples were collected before surgery (baseline) and three weeks after surgery. The primary objective was to assess the potential association between postoperative circulating tumour DNA (ctDNA) detection and recurrence of disease for patients with resectable CRLM within one year after resection. The secondary objective was the association between recurrence of disease within one year and detection of circulating tumour cells (CTCs). Baseline ctDNA was measured by next generation sequencing using a targeted panel (Oncomine Colon cell-free DNA assay) and postoperatively by digital PCR on genetic variants found preoperatively with the Oncomine panel. CTCs were enumerated using the FDA-approved CellSearch system.
FINDINGS: ctDNA was detected in 117/187 patients (63%) at baseline, and 28/104 evaluable patients (27%) still had detectable ctDNA postoperatively. CTC enumeration resulted in positivity for 37/183 patients (20%) at baseline and 14/158 patients (9%) postoperatively. No association was found between 1-year recurrence-free survival (RFS) and the presence of CTCs or ctDNA at baseline. In contrast, patients with postoperative undetectable ctDNA had a significantly improved 1-year RFS compared to patients with postoperative ctDNA (54% [95% CI 44%-67%] vs. 25% [95% CI 13%-47%], log-rank p = 0.0011). Similarly, patients with postoperative detectable CTCs had a significantly shorter 1-year RFS compared to patients without postoperative CTCs (15% [95% CI 4%-55%] vs. 53% [95% CI 45%-62%], log-rank p 0.0004). Also in multivariable analysis, detectable ctDNA and CTCs after surgery remained independently associated with a shorter 1-year RFS (HR 2.35; 95% CI 1.34-4.11; p = 0.0028 and HR 2.98; 95% CI 1.56-5.71; p = 0.0010, respectively).
INTERPRETATION: This is the first study conducted in patients with resectable CRLM without (neo)adjuvant chemotherapy, which demonstrates the impact of postoperative detectable circulating tumour load on 1-year RFS. Postoperative ctDNA and CTC detection both represent strong, independent predictors for a shorter RFS after local treatment, as opposed to preoperative detection.
FUNDING: This work was supported by KWF Kankerbestrijding (Dutch Cancer Society, EMCR 2014-6340).
PMID:40838198 | PMC:PMC12361997 | DOI:10.1016/j.eclinm.2025.103406
Ann Rheum Dis. 2025 Aug 20:S0003-4967(25)04249-9. doi: 10.1016/j.ard.2025.07.016. Online ahead of print.
ABSTRACT
OBJECTIVES: Catastrophic antiphospholipid syndrome (CAPS) is a complement-driven thrombotic disorder, characterised by widespread thrombosis and multiorgan failure. We identified rare germline variants including complement receptor 1 (CR1) in 50% of patients with CAPS. Here, we define CR1 dysregulation mechanisms (genetic/epigenetic) underlying complement-mediated thrombosis in CAPS and support C5 inhibition as a potential therapy.
METHODS: We quantified CR1 expression by flow cytometry across haematopoietic cell types. CRISPR/Cas9 genome editing of TF-1 (erythroleukaemia) cells was performed to generate CR1 'knock-out' and 'knock-in' lines with patient-specific CR1 variants. Multiomics analysis was performed to investigate the role of methylation in patients with reduced CR1 expression. Functional impact of low CR1 was assessed by complement-mediated cell killing using modified Ham assay, cell-bound complement degradation products through flow cytometry, and circulatory immune complexes in serum samples through ELISA.
RESULTS: CR1 expression in erythrocytes was markedly reduced on CAPS erythrocytes (n = 9, 21.80%) compared to healthy controls (HCs; n = 35, 84.04%), with promoter hypermethylation emerging as a plausible epigenetic mechanism for CR1 downregulation. Novel germline variant (CR1-V2125L; rs202148801) mitigated CR1 expression and increased complement-mediated cell death of knock-in cell lines. Erythrocytes from the patient with the CR1-V2125L variant had low CR1 expression. Levels of circulating immune complexes, which are bound and cleared by CR1 on erythrocytes, were higher in acute CAPS (n = 3, 25.55 µg Eq/mL) than HCs (n = 3, 7.445 µg Eq/mL). Five patients were treated with C5 inhibition which mitigated thrombosis.
CONCLUSIONS: Genetic or epigenetic-mediated CR1 deficiency is a potential hallmark of CAPS and predicts response to C5 inhibition.
PMID:40841298 | DOI:10.1016/j.ard.2025.07.016
Breathe (Sheff). 2025 Aug 19;21(3):250051. doi: 10.1183/20734735.0051-2025. eCollection 2025 Jul.
ABSTRACT
Lung cancer is the leading cause of cancer-related mortality worldwide, with nonsmall cell lung cancer (NSCLC) accounting for the majority of cases. Despite advancements in therapeutics, outcomes remain poor due to late-stage diagnoses and the molecular complexity of the disease. Liquid biopsy, a minimally invasive diagnostic approach, has emerged as a potentially transformative tool in lung cancer. The detection of tumour-derived biomarkers, such as circulating-tumour DNA, circulating tumour cells and exosomes, can be analysed for molecular profiling, early detection and monitoring of disease progression. There have been significant advancements of liquid biopsy technologies, such as next-generation sequencing and droplet digital PCR, that identify actionable mutations, detect resistance mechanisms and improve therapeutic outcomes. While there are still challenges like detecting early-stage disease and the risk of false positives, the combination of multi-omics data and artificial intelligence has the potential for more personalised and precise cancer treatments. Liquid biopsy represents a paradigm shift in the early detection and personalised treatment of lung cancer, offering significant potential to improve patient outcomes.
PMID:40837417 | PMC:PMC12362143 | DOI:10.1183/20734735.0051-2025
Google has just released a technical report detailing how much energy its Gemini apps use for each query. In total, the median prompt—one that falls in the middle of the range of energy demand—consumes 0.24 watt-hours of electricity, the equivalent of running a standard microwave for about one second. The company also provided average estimates for the water consumption and carbon emissions associated with a text prompt to Gemini.
It’s the most transparent estimate yet from a Big Tech company with a popular AI product, and the report includes detailed information about how the company calculated its final estimate. As AI has become more widely adopted, there’s been a growing effort to understand its energy use. But public efforts to directly measure the energy used by AI have been hampered by a lack of full access to the operations of a major tech company.
Earlier this year, MIT Technology Review published a comprehensive series on AI and energy, at which time none of the major AI companies would reveal their per-prompt energy usage. Google’s new publication, at last, allows for a peek behind the curtain that researchers and analysts have long hoped for.
The study focuses on a broad look at energy demand, including the power used not only by the AI chips that run models but also by all the other infrastructure needed to support that hardware.
“We wanted to be quite comprehensive in all the things we included,” said Jeff Dean, Google’s chief scientist, in an exclusive interview with MIT Technology Review about the new report.
That’s significant, because in this measurement, the AI chips—in this case, Google’s custom TPUs, the company’s proprietary equivalent of GPUs—account for just 58% of the total electricity demand of 0.24 watt-hours.
Another large portion of the energy is used by equipment needed to support AI-specific hardware: The host machine’s CPU and memory account for another 25% of the total energy used. There’s also backup equipment needed in case something fails—these idle machines account for 10% of the total. The final 8% is from overhead associated with running a data center, including cooling and power conversion.
This sort of report shows the value of industry input to energy and AI research, says Mosharaf Chowdhury, a professor at the University of Michigan and one of the heads of the ML.Energy leaderboard, which tracks energy consumption of AI models.
Estimates like Google’s are generally something that only companies can produce, because they run at a larger scale than researchers are able to and have access to behind-the-scenes information. “I think this will be a keystone piece in the AI energy field,” says Jae-Won Chung, a PhD candidate at the University of Michigan and another leader of the ML.Energy effort. “It’s the most comprehensive analysis so far.”
Google’s figure, however, is not representative of all queries submitted to Gemini: The company handles a huge variety of requests, and this estimate is calculated from a median energy demand, one that falls in the middle of the range of possible queries.
So some Gemini prompts use much more energy than this: Dean gives the example of feeding dozens of books into Gemini and asking it to produce a detailed synopsis of their content. “That’s the kind of thing that will probably take more energy than the median prompt,” he says. Using a reasoning model could also have a higher associated energy demand because these models take more steps before producing an answer.
This report was also strictly limited to text prompts, so it doesn’t represent what’s needed to generate an image or a video. (Other analyses, including one in MIT Technology Review’s Power Hungry series earlier this year, show that these tasks can require much more energy.)
The report also finds that the total energy used to field a Gemini query has fallen dramatically over time. The median Gemini prompt used 33 times more energy in May 2024 than it did in May 2025, according to Google. The company points to advancements in its models and other software optimizations for the improvements.
Google also estimates the greenhouse-gas emissions associated with the median prompt, which they put at 0.03 grams of carbon dioxide. To get to this number, the company multiplied the total energy used to respond to a prompt by the average emissions per unit of electricity.
Rather than using an emissions estimate based on the US grid average, or the average of the grids where Google operates, the company instead uses a market-based estimate, which takes into account electricity purchases that the company makes from clean energy projects. The company has signed agreements to buy over 22 gigawatts of power from sources including solar, wind, geothermal, and advanced nuclear projects since 2010. Because of those purchases, Google’s emissions per unit of electricity on paper are roughly one-third of those on the average grid where it operates.
AI data centers also consume water for cooling, and Google estimates that each prompt consumes 0.26 milliliters of water, or about five drops.
The goal of this work was to provide users a window into the energy use of their interactions with AI, Dean says.
“People are using [AI tools] for all kinds of things, and they shouldn’t have major concerns about the energy usage or the water usage of Gemini models, because in our actual measurements, what we were able to show was that it’s actually equivalent to things you do without even thinking about it on a daily basis,” he says, “like watching a few seconds of TV or consuming five drops of water.”
The publication greatly expands what’s known about AI’s resource usage. It follows recent increasing pressure on companies to release more information about the energy toll of the technology. “I’m really happy that they put this out,” says Sasha Luccioni, an AI and climate researcher at Hugging Face. “People want to know what the cost is.”
This estimate and the supporting report contain more public information than has been available before, and it’s helpful to get more information about AI use in real life, at scale, by a major company, Luccioni adds. However, there are still details that the company isn’t sharing in this report. One major question mark is the total number of queries that Gemini gets each day, which would allow estimates of the AI tool’s total energy demand.
And ultimately, it’s still the company deciding what details to share, and when and how. “We’ve been trying to push for a standardized AI energy score,” Luccioni says, a standard for AI similar to the Energy Star rating for appliances. “This is not a replacement or proxy for standardized comparisons.”
OMICS. 2025 Aug 19. doi: 10.1177/15578100251366980. Online ahead of print.
ABSTRACT
Ferroptosis, an iron-dependent form of oxidative cell death, plays a critical role in cancer progression and immune regulation. However, the functional connections of ferroptosis with specific immune cell types remain poorly defined, limiting the future possibilities to harness ferroptosis for cancer biology, diagnosis, and treatment. To address this knowledge gap, we conducted an integrated transcriptomic analysis to investigate ferroptosis-related immune dynamics in gastric cancer (GC). We utilized GC datasets from The Cancer Genome Atlas-stomach adenocarcinoma (n = 412) and the GSE66229 (n = 300) that were clustered into three GC immune subtypes based on single-sample Gene Set Enrichment Analysis scores of 29 immune gene sets. Bulk RNA-seq analysis revealed that the immune-inflamed subtype (HIS) of tumor samples in both GC datasets exhibited the highest ferroptosis enrichment and showed a positive correlation with activated mast cells and neutrophils. Given the regulatory role of mast cells in the tumor microenvironment (TME), particularly in recruiting neutrophils, we further examined their link to ferroptosis. In a fibroblast-mast cell coculture RNA-seq data (GSE223179), fibroblasts exhibited increased ferroptosis enrichment, supporting a mast cell-mediated influence. Single-cell RNA-seq data confirmed stronger interactions between mast cells and fibroblasts in GC compared to normal tissues. Specifically, they revealed a positive correlation between mast cell activity and ferroptosis enrichment in tumor-associated fibroblasts. In conclusion, these findings suggest that mast cells may promote ferroptosis in the TME through paracrine signaling, possibly via annexin and cyclophilin A. By uncovering this novel pathophysiological axis, our study reveals a previously unrecognized role of mast cells in regulating ferroptosis within the TME. The findings call for translational and experimental medical research and have potential implications for innovation toward GC diagnostics and therapeutics.
PMID:40831393 | DOI:10.1177/15578100251366980
Nature Biotechnology, Published online: 19 August 2025; doi:10.1038/s41587-025-02770-1
A vast landscape of ‘undruggable’ cancer targets remains beyond the reach of conventional therapeutic agents. Recent advances in artificial intelligence (AI), however, are challenging this paradigm. Synthesizing insights from a Cancer Moonshot workshop, we argue that systemically addressing the undruggable target space with AI requires a new conceptual framework. We highlight the failure of current target taxonomies and the need for benchmarking datasets, and re-evaluate clinical validation for novel AI-driven modalities.
J Clin Microbiol. 2025 Aug 19:e0058525. doi: 10.1128/jcm.00585-25. Online ahead of print.
ABSTRACT
Human papillomavirus (HPV) is comprised of >200 genotypes and has an ~8 kb, circular, double-stranded DNA genome. Transmission of HPV occurs through skin-to-skin contact and infection of squamous epithelial cells of cutaneous and mucosal surfaces. HPV genotypes are categorized as low- or high-risk (hrHPV) based on oncogenic potential. There are approximately 14 types of hrHPV that can cause several types of cancer, including HPV-associated oropharyngeal squamous cell carcinoma (HPV(+)OPSCC). Detection of HPV(+)OPSCC is traditionally accomplished using p16 immunohistochemistry (IHC) and HPV-specific testing, either DNA or RNA in situ hybridization (ISH) staining or DNA-based PCR of suspected tumor biopsy tissue. More recently, platelet-poor plasma (PPP) samples from patients with HPV(+)OPSCC have proven useful for detection and quantitation of fragments of HPV circulating tumor DNA (ctDNA). ctDNA has been shown to be useful in determining treatment response and monitoring for disease recurrence. In this study, a novel droplet digital PCR assay (ddPCR) was developed and validated for the detection and quantitation of ctDNA from 5 hrHPV genotypes in PPP. Analytical sensitivity ranged from 7.71 to 19.45 fragments of HPV ctDNA per milliliter of PPP across five hrHPV genotypes. In patients with confirmed primary or recurrent HPV(+)OPSCC or HPV(-)OPSCC, testing of corresponding PPP samples (n = 32) by ddPCR demonstrated 90.63% (29/32) overall agreement with p16/HPV-ISH biopsy results. Compared with reference ddPCR assays performed at outside laboratories, our ddPCR assay yielded 90% (9/10) overall agreement. This assay may provide clinicians with a tool for monitoring HPV ctDNA prior to, during, and after treatment of an HPV-associated cancer.
IMPORTANCE: At least 14 genotypes of human papillomavirus (HPV) have been identified to have high oncogenic potential. While molecular diagnostic testing for HPV is widely available for liquid cytologic cervical samples, testing is limited for other sample types, including liquid biopsy samples, such as platelet-poor plasma (PPP). With the rising incidence of HPV-associated oropharyngeal squamous cell carcinoma (HPV(+)OPSCC), laboratory testing is an essential part of patient diagnosis, management, and surveillance. Here, we summarize the development and analytical performance validation of a multiplexed, droplet digital PCR (ddPCR) assay for the detection and quantitation of HPV circulating tumor DNA (ctDNA) in PPP. This assay may provide clinicians with a tool to address minimal residual disease for patients with an HPV-associated cancer.
PMID:40827899 | DOI:10.1128/jcm.00585-25
Expert Rev Anticancer Ther. 2025 Aug 18. doi: 10.1080/14737140.2025.2549538. Online ahead of print.
ABSTRACT
INTRODUCTION: In the era of precision medicine, molecular biomarker testing is increasingly becoming standard of care for Non-Small Cell Lung Cancer (NSCLC) patients. Tissue and liquid biopsy-based Next-Generation Sequencing (NGS) is now highly recommended.
AREAS COVERED: Different NGS platforms emerged as a cost-effective strategy to perform a massive and parallel sequencing performing higher technical sensitivity than old generation technologies in detecting low abundant alterations in challenging diagnostic samples. NGS systems can detect single nucleotide variants (SNV), small insertions and deletions (indels), copy number alterations (CNAs) and structural variants (SVs) or gene fusions across selected druggable genes optimizing clinical administration of NSCLC patients. The diagnostic implementation of the most adequate NGS panel depending on several factors that could impact on the clinical utility of testing assay.
EXPERT OPINION: Promising advanced technologies are emerging as potentially integrative tools in personalized medicine. In this context, multi-omic evaluation including genomic, transcriptomic, fragmentomic and epigenomic signatures are under investigation to significantly modify clinical algorithm of NSCLC patients. On this basis, sequencing strategies may play a pivotal role in the implementation of a new predictive model for cancer diagnosis and prognosis.
PMID:40823981 | DOI:10.1080/14737140.2025.2549538

Victor Dibia shares insights into multi-agent systems. He explains their definition, demonstrates implementation using the AutoGen framework, and identifies 10 common reasons these systems fail in production. He provides guidance on when a multi-agent approach is appropriate, emphasizing evaluation-driven design and tool-focused implementations.
By Victor Dibia
Transl Lung Cancer Res. 2025 Jul 31;14(7):2369-2373. doi: 10.21037/tlcr-2025-523. Epub 2025 Jul 17.
NO ABSTRACT
PMID:40799451 | PMC:PMC12337028 | DOI:10.21037/tlcr-2025-523
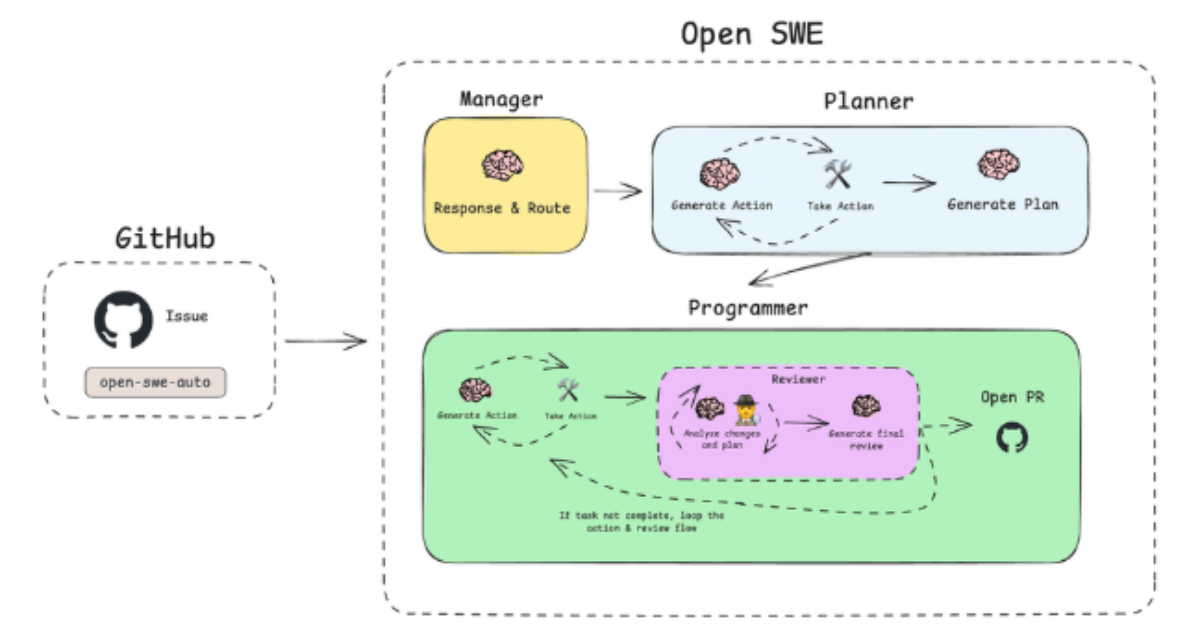
LangChain has released Open SWE, a fully open-source, asynchronous coding agent designed to operate in the cloud and handle complex software development tasks. The company says Open SWE represents a shift away from real-time “copilot” assistants toward more autonomous, long-running agents that integrate directly with a developer’s existing workflows.
By Robert Krzaczyński
Nature, Published online: 13 August 2025; doi:10.1038/s41586-025-09398-w
A study presents ALPACA, a computational method for inferring clone- and allele-specific copy numbers of individual clones from multi-sample bulk DNA-sequencing data, and demonstrates its use to study metastasis trajectories.
Artificial intelligence models that can discover drugs and write code still fail at puzzles a lay person can master in minutes. This phenomenon sits at the heart of the challenge of artificial general intelligence (AGI). Can today’s AI revolution produce models that rival or surpass human intelligence across all domains? If so, what underlying enablers—whether hardware, software, or the orchestration of both—would be needed to power them?
Dario Amodei, co-founder of Anthropic, predicts some form of “powerful AI” could come as early as 2026, with properties that include Nobel Prize-level domain intelligence; the ability to switch between interfaces like text, audio, and the physical world; and the autonomy to reason toward goals, rather than responding to questions and prompts as they do now. Sam Altman, chief executive of OpenAI, believes AGI-like properties are already “coming into view,” unlocking a societal transformation on par with electricity and the internet. He credits progress to continuous gains in training, data, and compute, along with falling costs, and a socioeconomic value that is
“super-exponential.”
Optimism is not confined to founders. Aggregate forecasts give at least a 50% chance of AI systems achieving several AGI milestones by 2028. The chance of unaided machines outperforming humans in every possible task is estimated at 10% by 2027, and 50% by 2047, according to one expert survey. Time horizons shorten with each breakthrough, from 50 years at the time of GPT-3’s launch to five years by the end of 2024. “Large language and reasoning models are transforming nearly every industry,” says Ian Bratt, vice president of machine learning technology and fellow at Arm.
This content was produced by Insights, the custom content arm of MIT Technology Review. It was not written by MIT Technology Review’s editorial staff.
This content was researched, designed, and written entirely by human writers, editors, analysts, and illustrators. This includes the writing of surveys and collection of data for surveys. AI tools that may have been used were limited to secondary production processes that passed thorough human review.
