 Login
Google launches new protocol for agent-driven purchases
16 September 2025 at 21:00
Called the Agent Payments Protocol (AP2), the system is meant to be interoperable between AI platforms, payment systems and vendors.


Nature, Published online: 15 September 2025; doi:10.1038/d41586-025-02940-w
Developers of griefbots say that they help people by allowing them to commune with recreations of the dead, but others say that the technology is fraught with danger.

Hugging Face has unveiled FinePDFs, the largest publicly available corpus built entirely from PDFs. The dataset spans 475 million documents in 1,733 languages, totaling roughly 3 trillion tokens. At 3.65 terabytes in size, FinePDFs introduces a new dimension to open training datasets by tapping into a resource long considered too complex and expensive to process.
By Robert Krzaczyński
Nature Medicine, Published online: 15 September 2025; doi:10.1038/s41591-025-03965-4
A brief, self-administered digital cognitive test, in combination with a blood test, accurately detects clinical Alzheimer’s disease in primary care.
Cancers (Basel). 2025 Aug 29;17(17):2831. doi: 10.3390/cancers17172831.
ABSTRACT
Background: Hormone receptor-positive (HR+), HER2-negative breast cancer accounts for the majority of breast cancer diagnoses. While outcomes have improved with neoadjuvant and adjuvant therapies, the risk of late recurrence persists, and there remains a critical need for reliable biomarkers to guide prognosis and post-treatment surveillance. Circulating tumor DNA (ctDNA), detectable via liquid biopsy, has emerged as a promising tool for monitoring minimal residual disease and predicting survival outcomes. This systematic review evaluates the association between ctDNA detection during neoadjuvant or adjuvant treatment and survival outcomes in early-stage HR+/HER2- breast cancer. Methods: This systematic review was conducted in accordance with PRISMA guidelines. A comprehensive literature search of Ovid MEDLINE and Embase was conducted to identify studies published through 3 May 2024 that evaluated ctDNA as a prognostic biomarker in stage I-III HR+/HER2- breast cancer. We included studies reporting recurrence-free survival, invasive disease-free survival, or overall survival and excluded non-original studies, conference abstracts, and non-English articles. Data extraction and qualitative synthesis were performed, and the risk of bias was qualitatively assessed across studies. No review protocol was registered. Results: Eleven studies comprising 1644 patients met the inclusion criteria. In the neoadjuvant setting, ctDNA positivity prior to treatment initiation was associated with inferior survival outcomes. In the adjuvant setting, detection of ctDNA during or after treatment was consistently linked to poorer recurrence-free and invasive disease-free survival. Across studies, ctDNA detection was a significant negative prognostic marker. Conclusions: This systematic review supports the prognostic value of ctDNA in HR+/HER2- early-stage breast cancer. Limitations include small sample sizes, observational study designs, and heterogeneity in ctDNA assays. Standardization of ctDNA testing methods and further prospective trials are needed to validate its clinical utility and explore its potential role in guiding therapeutic interventions.
PMID:40940926 | PMC:PMC12427406 | DOI:10.3390/cancers17172831
Nature Medicine, Published online: 11 September 2025; doi:10.1038/s41591-025-03936-9
In an irrevocably changed landscape, reform of the global health system needs to answer key questions on functions, what should be delivered in different contexts and at different levels, and how the system should operate.
Int J Mol Sci. 2025 Aug 31;26(17):8472. doi: 10.3390/ijms26178472.
ABSTRACT
Lung cancer is the leading cause of cancer mortality globally, despite the advancements in screening and management. Survival rates for lung cancer remain suboptimal, largely due to late-stage diagnoses and tumor heterogeneity. Recent advancements in artificial intelligence and radiomics provide a promising outlook for lung cancer screening, diagnosis, personalized treatment, and prognosis. These advances use large-scale clinical and imaging datasets that help identify patterns and predictive features that may be missed by human interpretation. Artificial intelligence tools hold the potential to take clinical decision-making to another level, thus improving patient outcomes. This review summarizes current evidence on the applications, challenges, and future directions of artificial intelligence (AI) in lung cancer care, with an emphasis on early diagnosis and personalized treatment. We examine recent developments in AI-driven approaches, including machine learning and deep neural networks, applied to imaging (radiomics), histopathology, biomarker analysis, and multi-omic data integration. AI-based models demonstrate promising performance in early detection, risk stratification, molecular profiling (e.g., programmed death-ligand 1 (PD-L1) and epidermal growth factor receptor (EGFR) status), and outcome prediction. These tools may enhance diagnostic accuracy, optimize therapeutic decisions, and ultimately improve patient outcomes. However, significant challenges remain, including model heterogeneity, limited external validation, generalizability issues, and ethical concerns related to transparency and clinical accountability. AI holds transformative potential for lung cancer care but requires further validation, standardization, and integration into clinical workflows. Multicenter collaborations, regulatory frameworks, and explainable AI models will be essential for successful clinical adoption.
PMID:40943394 | PMC:PMC12429163 | DOI:10.3390/ijms26178472
Chest. 2025 Sep;168(3):581-583. doi: 10.1016/j.chest.2025.04.023.
NO ABSTRACT
PMID:40935546 | DOI:10.1016/j.chest.2025.04.023
MIT Technology Review Explains: Let our writers untangle the complex, messy world of technology to help you understand what’s coming next. You can read more from the series here.
It’s been a big year for video generation. In the last nine months OpenAI made Sora public, Google DeepMind launched Veo 3, the video startup Runway launched Gen-4. All can produce video clips that are (almost) impossible to distinguish from actual filmed footage or CGI animation. This year also saw Netflix debut an AI visual effect in its show The Eternaut, the first time video generation has been used to make mass-market TV.
Sure, the clips you see in demo reels are cherry-picked to showcase a company’s models at the top of their game. But with the technology in the hands of more users than ever before—Sora and Veo 3 are available in the ChatGPT and Gemini apps for paying subscribers—even the most casual filmmaker can now knock out something remarkable.
The downside is that creators are competing with AI slop, and social media feeds are filling up with faked news footage. Video generation also uses up a huge amount of energy, many times more than text or image generation.
With AI-generated videos everywhere, let’s take a moment to talk about the tech that makes them work.
Let’s assume you’re a casual user. There are now a range of high-end tools that allow pro video makers to insert video generation models into their workflows. But most people will use this technology in an app or via a website. You know the drill: “Hey, Gemini, make me a video of a unicorn eating spaghetti. Now make its horn take off like a rocket.” What you get back will be hit or miss, and you’ll typically need to ask the model to take another pass or 10 before you get more or less what you wanted.
So what’s going on under the hood? Why is it hit or miss—and why does it take so much energy? The latest wave of video generation models are what’s known as latent diffusion transformers. Yes, that’s quite a mouthful. Let’s unpack each part in turn, starting with diffusion.
Imagine taking an image and adding a random spattering of pixels to it. Take that pixel-spattered image and spatter it again and then again. Do that enough times and you will have turned the initial image into a random mess of pixels, like static on an old TV set.
A diffusion model is a neural network trained to reverse that process, turning random static into images. During training, it gets shown millions of images in various stages of pixelation. It learns how those images change each time new pixels are thrown at them and, thus, how to undo those changes.
The upshot is that when you ask a diffusion model to generate an image, it will start off with a random mess of pixels and step by step turn that mess into an image that is more or less similar to images in its training set.
But you don’t want any image—you want the image you specified, typically with a text prompt. And so the diffusion model is paired with a second model—such as a large language model (LLM) trained to match images with text descriptions—that guides each step of the cleanup process, pushing the diffusion model toward images that the large language model considers a good match to the prompt.
An aside: This LLM isn’t pulling the links between text and images out of thin air. Most text-to-image and text-to-video models today are trained on large data sets that contain billions of pairings of text and images or text and video scraped from the internet (a practice many creators are very unhappy about). This means that what you get from such models is a distillation of the world as it’s represented online, distorted by prejudice (and pornography).
It’s easiest to imagine diffusion models working with images. But the technique can be used with many kinds of data, including audio and video. To generate movie clips, a diffusion model must clean up sequences of images—the consecutive frames of a video—instead of just one image.
All this takes a huge amount of compute (read: energy). That’s why most diffusion models used for video generation use a technique called latent diffusion. Instead of processing raw data—the millions of pixels in each video frame—the model works in what’s known as a latent space, in which the video frames (and text prompt) are compressed into a mathematical code that captures just the essential features of the data and throws out the rest.
A similar thing happens whenever you stream a video over the internet: A video is sent from a server to your screen in a compressed format to make it get to you faster, and when it arrives, your computer or TV will convert it back into a watchable video.
And so the final step is to decompress what the latent diffusion process has come up with. Once the compressed frames of random static have been turned into the compressed frames of a video that the LLM guide considers a good match for the user’s prompt, the compressed video gets converted into something you can watch.
With latent diffusion, the diffusion process works more or less the way it would for an image. The difference is that the pixelated video frames are now mathematical encodings of those frames rather than the frames themselves. This makes latent diffusion far more efficient than a typical diffusion model. (Even so, video generation still uses more energy than image or text generation. There’s just an eye-popping amount of computation involved.)
Still with me? There’s one more piece to the puzzle—and that’s how to make sure the diffusion process produces a sequence of frames that are consistent, maintaining objects and lighting and so on from one frame to the next. OpenAI did this with Sora by combining its diffusion model with another kind of model called a transformer. This has now become standard in generative video.
Transformers are great at processing long sequences of data, like words. That has made them the special sauce inside large language models such as OpenAI’s GPT-5 and Google DeepMind’s Gemini, which can generate long sequences of words that make sense, maintaining consistency across many dozens of sentences.
But videos are not made of words. Instead, videos get cut into chunks that can be treated as if they were. The approach that OpenAI came up with was to dice videos up across both space and time. “It’s like if you were to have a stack of all the video frames and you cut little cubes from it,” says Tim Brooks, a lead researcher on Sora.
Using transformers alongside diffusion models brings several advantages. Because they are designed to process sequences of data, transformers also help the diffusion model maintain consistency across frames as it generates them. This makes it possible to produce videos in which objects don’t pop in and out of existence, for example.
And because the videos are diced up, their size and orientation do not matter. This means that the latest wave of video generation models can be trained on a wide range of example videos, from short vertical clips shot with a phone to wide-screen cinematic films. The greater variety of training data has made video generation far better than it was just two years ago. It also means that video generation models can now be asked to produce videos in a variety of formats.
A big advance with Veo 3 is that it generates video with audio, from lip-synched dialogue to sound effects to background noise. That’s a first for video generation models. As Google DeepMind CEO Demis Hassabis put it at this year’s Google I/O: “We’re emerging from the silent era of video generation.”
The challenge was to find a way to line up video and audio data so that the diffusion process would work on both at the same time. Google DeepMind’s breakthrough was a new way to compress audio and video into a single piece of data inside the diffusion model. When Veo 3 generates a video, its diffusion model produces audio and video together in a lockstep process, ensuring that the sound and images are synched.
No—or at least not yet. Diffusion models are most often used to generate images, video, and audio. Large language models—which generate text (including computer code)—are built using transformers. But the lines are blurring. We’ve seen how transformers are now being combined with diffusion models to generate videos. And this summer Google DeepMind revealed that it was building an experimental large language model that used a diffusion model instead of a transformer to generate text.
Here’s where things start to get confusing: Though video generation (which uses diffusion models) consumes a lot of energy, diffusion models themselves are in fact more efficient than transformers. Thus, by using a diffusion model instead of a transformer to generate text, Google DeepMind’s new LLM could be a lot more efficient than existing LLMs. Expect to see more from diffusion models in the near future!
Nature, Published online: 11 September 2025; doi:10.1038/d41586-025-02936-6
Authors and peer reviewers are failing to disclose the use of LLMs despite journal policies limiting their use.
Nature, Published online: 10 September 2025; doi:10.1038/s41586-025-09374-4
Cancer evolutionary dynamics are quantitatively inferred using a method, EVOFLUx, applied to fluctuating DNA methylation.
Nature, Published online: 10 September 2025; doi:10.1038/d41586-025-02911-1
Representatives of four medical research centres have told Nature they have waived normal ethical review because ‘synthetic’ data do not contain real or traceable patient information.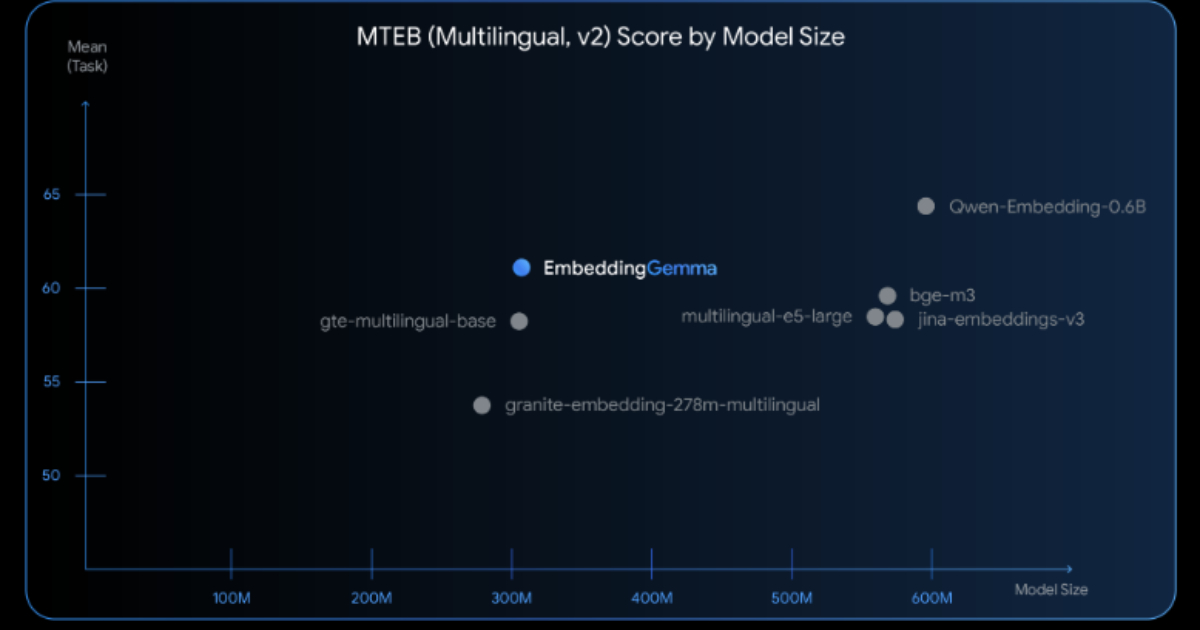
Google DeepMind has introduced EmbeddingGemma, a 308M parameter open embedding model designed to run efficiently on-device. The model aims to make applications like retrieval-augmented generation (RAG), semantic search, and text classification accessible without the need for a server or internet connection.
By Robert Krzaczyński
Nature, Published online: 10 September 2025; doi:10.1038/d41586-025-02813-2
From large national databases to bespoke sample collections, biobanks offer a wealth of avenues for scientific enquiry.
Sci Adv. 2025 Sep 12;11(37):eady0080. doi: 10.1126/sciadv.ady0080. Epub 2025 Sep 10.
ABSTRACT
Cell type-specific regulatory programs that drive type 1 diabetes (T1D) in the pancreas are poorly understood. Here, we performed single-nucleus multiomics and spatial transcriptomics in up to 32 nondiabetic (ND), autoantibody-positive (AAB+), and T1D pancreas donors. Genomic profiles from 853,005 cells mapped to 12 pancreatic cell types, including multiple exocrine subtypes. β, Acinar, and other cell types, and related cellular niches, had altered abundance and gene activity in T1D progression, including distinct pathways altered in AAB+ compared to T1D. We identified epigenomic drivers of gene activity in T1D and AAB+ which, combined with genetic association, revealed causal pathways of T1D risk including antigen presentation in β cells. Last, single-cell and spatial profiles together revealed widespread changes in cell-cell signaling in T1D including signals affecting β cell regulation. Overall, these results revealed drivers of T1D in the pancreas, which form the basis for therapeutic targets for disease prevention.
PMID:40929272 | PMC:PMC12422192 | DOI:10.1126/sciadv.ady0080
