❌

Normal view

Impact of Digital Interventions on the Treatment Burden of Patients With Chronic Conditions: Systematic Review

Background: Digital interventions can provide cost-effective, quality health care for patients with chronic conditions. Patients with chronic conditions often are burdened by a substantial load of adhering to a treatment regimen and suffer from impacts on their function and well-being. This treatment burden has consequences for treatment adherence and disease outcomes. Digital interventions have the potential to alleviate the burden, but they also may cause new challenges and an increased workload for the patient. Previous reviews have examined digital interventions or treatment burden separately, but there is a lack of systematic reviews on the intersection of digital interventions, treatment burden, and chronic conditions. Objective: This systematic review aimed to evaluate the evidence of how digital interventions impact the treatment burden experienced by people with chronic conditions, and to assess the quality of this evidence. Methods: We searched databases PubMed, Scopus, Web of Science, ACM, PubMed Central, and CINAHL for articles published between January 1, 2013, and June 17, 2025. We included studies that had key topics related to chronic conditions, treatment burden, and digital interventions. A total of 2 reviewers independently screened the articles in 2 stages, extracted data on study design, participant characteristics, intervention type, and treatment burden outcomes from included articles, and assessed their quality using the Critical Appraisal tools from the Joanna Briggs Institute. A convergent integrated approach was used for data synthesis and integration, where quantitative data were converted into qualitative data, and the qualitative and quantitative evidence were analyzed and categorized together. Results: We included 46 relevant studies in total. We categorized the interventions into 4 types: Telehealth, informational resources, self-management tools, and facilitated tools. The results of this study indicate that digital interventions mostly support patients with chronic conditions with their treatment burden, with minor concerns of increasing treatment burden. The main benefits are support with self-management, informational support, and easier ways to contact health care professionals. The main concerns were accessibility issues, time-consuming tools, and causing fear and anxiety. Conclusions: Our findings demonstrate how treatment burden is a relevant concept for future digital health care research and practice. Digital interventions can help patients with their treatment burden by supporting self-management, improving access to health care, improving patients’ experience, and addressing relevant concerns. More research is needed about conditions with low or medium initial treatment burden.
Organoid-based precision cancer modeling: New frontier in lung cancer research

22 November 2025 at 19:00

Cell Rep. 2025 Nov 20;44(12):116595. doi: 10.1016/j.celrep.2025.116595. Online ahead of print.

ABSTRACT

Lung cancer remains a leading cause of cancer-related mortality globally, underscoring the need for advanced preclinical models that accurately recapitulate disease biology. Recent advances in organoid technology have enabled the establishment of patient-derived lung cancer organoids (LCOs), which faithfully reproduce the histological, genetic, and phenotypic features of primary tumors. This organoid-based precision modeling facilitates deeper insights into tumor biology and disease progression, supporting the identification of novel therapeutic targets and biomarkers. In this review, we summarize recent progress in LCO-based precision modeling, focusing on their ability to preserve tumor heterogeneity, link genotype and phenotype through multi-omics integration, and explore tumor-microenvironment interactions via gene editing and co-culture systems. We also highlight the growing importance of LCO biobanks and international collaborations in translational research. Despite challenges such as low establishment efficiency, LCO-based precision modeling offers a powerful platform for understanding lung cancer pathogenesis and guiding the development of more effective therapies.

PMID:41273722 | DOI:10.1016/j.celrep.2025.116595

  • ✇InfoQ
  • Olmo 3 Release Provides Full Transparency into Model Development and Training Robert Krzaczyński
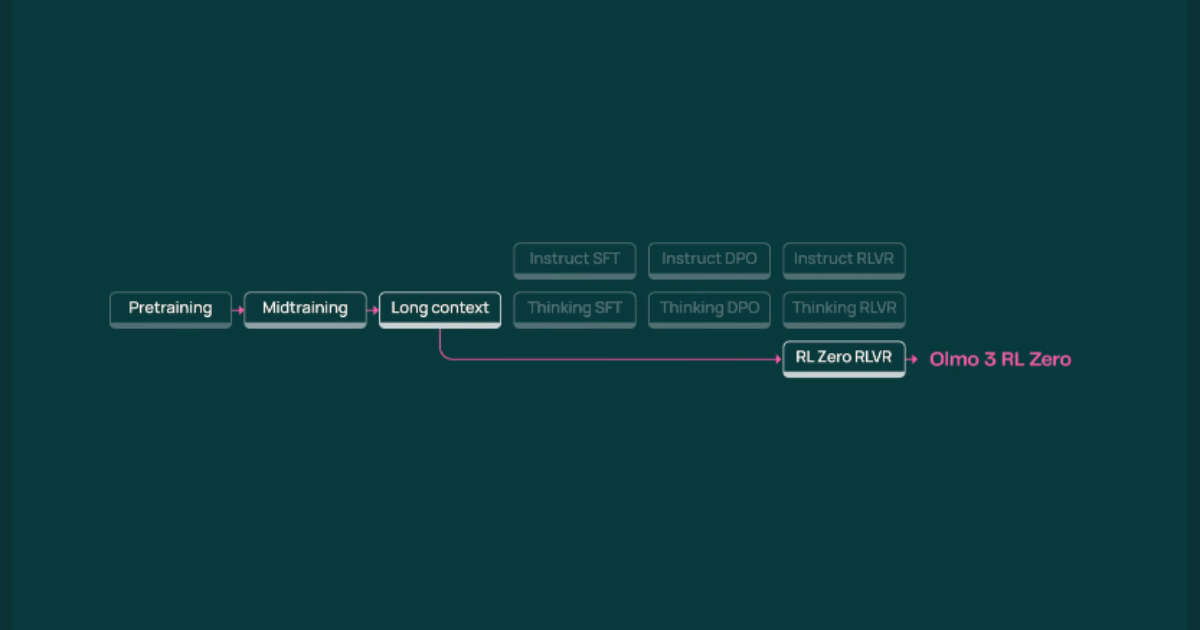
    The Allen Institute for AI has unveiled Olmo 3, an open-source language model family that empowers developers with full access to the model lifecycle, from training datasets to checkpoints. Featuring reasoning-focused variants and robust tools for post-training modifications, Olmo 3 promotes transparency, experimentation, and community collaboration, driving innovations in AI. By Robert Krzaczyński
     

Olmo 3 Release Provides Full Transparency into Model Development and Training

23 November 2025 at 00:00

The Allen Institute for AI has unveiled Olmo 3, an open-source language model family that empowers developers with full access to the model lifecycle, from training datasets to checkpoints. Featuring reasoning-focused variants and robust tools for post-training modifications, Olmo 3 promotes transparency, experimentation, and community collaboration, driving innovations in AI.

By Robert Krzaczyński

Pan-cancer prevalence, risk, and clinical and demographic characteristics of Lynch Syndrome-associated variants in BioBank Japan

Commun Med (Lond). 2025 Nov 13. doi: 10.1038/s43856-025-01231-9. Online ahead of print.

ABSTRACT

BACKGROUND: Although germline testing for DNA mismatch repair (MMR) genes is routinely performed, clinical guidelines highlight evidence gaps due to limited populations and biases. We examined germline pathogenic variants of MMR genes (MLH1, MSH2, MSH6, and PMS2) in 112,927 unselected individuals from BioBank Japan.

METHODS: We analyzed 74,085 cancer patients with 23 cancer types and 38,842 controls matched by sex, age, and hospital area from BioBank Japan, collected between April 2003 and March 2018. Germline pathogenic variants in the coding regions and 2 bp flanking intronic sequences of MMR genes were identified using a multiplex PCR-based target sequencing method. We examined associations with cancer types and demographic characterization of the pathogenic variants, comparing findings to existing clinical guidelines.

RESULTS: Here we show 228 pathogenic variants identified in MMR genes, with pathogenic MSH6 variants most frequently observed in endometrial cancer and 12 other significant associations. Twelve other significant associations are noted across a broad range of odds ratios, whereas pancreatic cancer exhibits no such association. Pathogenic variant carriers are diagnosed up to 12.4 years earlier than non-carriers, and colorectal and gastric cancers are diagnosed up to 16.4 years later than indicated by the guidelines. Higher carrier frequencies are observed in patients with both colorectal and endometrial cancers (24.8%) and in those with endometrial cancer and a family history of endometrial (26.0%) or colorectal (16.1%) cancers.

CONCLUSIONS: This study provides critical insights for clinical guidelines on the associations between cancer types, age at diagnosis, and carrier frequency.

PMID:41258140 | DOI:10.1038/s43856-025-01231-9

Latent plasticity of the human pancreas across development, health, and disease

bioRxiv [Preprint]. 2025 Oct 3:2025.10.01.679230. doi: 10.1101/2025.10.01.679230.

ABSTRACT

The pancreas plays a central role in major human diseases, yet our understanding of its cellular diversity and plasticity remains incomplete. Here, we present a single-cell multiomics atlas of the human pancreas, profiling over four million cells and nuclei from 57 donors across fetal development, adult homeostasis, and type 2 diabetes (T2D). Integrating sc/snRNA-seq, snATAC-seq, VASA-seq, spatial transcriptomics (Xenium), and multiplexed proteomics (CODEX), we resolve gene expression, chromatin accessibility, and spatial organization at high resolution. We identify transcriptionally plastic centroacinar-like cells (pCACs) in adults with fetal-like features, delineate endocrine and exocrine lineage trajectories during development, and uncover HNF1A-defined beta cell epigenetic states. In T2D, we observe shifts in beta cell subtypes and altered regulatory programs. Glucose perturbation of healthy islets reveals cell-type-specific adaptation and stress responses. This atlas provides a foundational framework to understand pancreas biology and the role of cellular plasticity in regeneration and disease.

PMID:41256699 | PMC:PMC12622017 | DOI:10.1101/2025.10.01.679230

Foundation Models in Medical Imaging: A Review and Outlook

arXiv:2506.09095v4 Announce Type: replace-cross Abstract: Foundation models (FMs) are changing the way medical images are analyzed by learning from large collections of unlabeled data. Instead of relying on manually annotated examples, FMs are pre-trained to learn general-purpose visual features that can later be adapted to specific clinical tasks with little additional supervision. In this review, we examine how FMs are being developed and applied in pathology, radiology, and ophthalmology, drawing on evidence from over 150 studies. We explain the core components of FM pipelines, including model architectures, self-supervised learning methods, and strategies for downstream adaptation. We also review how FMs are being used in each imaging domain and compare design choices across applications. Finally, we discuss key challenges and open questions to guide future research.

Embedding Explainable AI in NHS Clinical Safety: The Explainability-Enabled Clinical Safety Framework (ECSF)

arXiv:2511.11590v2 Announce Type: replace-cross Abstract: Artificial intelligence (AI) is increasingly embedded in NHS workflows, but its probabilistic and adaptive behaviour conflicts with the deterministic assumptions underpinning existing clinical-safety standards. DCB0129 and DCB0160 provide strong governance for conventional software yet do not define how AI-specific transparency, interpretability, or model drift should be evidenced within Safety Cases, Hazard Logs, or post-market monitoring. This paper proposes an Explainability-Enabled Clinical Safety Framework (ECSF) that integrates explainability into the DCB0129/0160 lifecycle, enabling Clinical Safety Officers to use interpretability outputs as structured safety evidence without altering compliance pathways. A cross-regulatory synthesis mapped DCB clauses to principles from Good Machine Learning Practice, the NHS AI Assurance and T.E.S.T. frameworks, and the EU AI Act. The resulting matrix links regulatory clauses, principles, ECSF checkpoints, and suitable explainability outputs. ECSF introduces five checkpoints: global transparency for hazard identification, case-level interpretability for verification, clinician usability for evaluation, traceable decision pathways for risk control, and longitudinal interpretability monitoring for post-market surveillance. Techniques such as SHAP, LIME, Integrated Gradients, saliency mapping, and attention visualisation are mapped to corresponding DCB artefacts. ECSF reframes explainability as a core element of clinical-safety assurance, bridging deterministic risk governance with the probabilistic behaviour of AI and supporting alignment with GMLP, the EU AI Act, and NHS AI Assurance principles.

CLINB: A Climate Intelligence Benchmark for Foundational Models

arXiv:2511.11597v1 Announce Type: new Abstract: Evaluating how Large Language Models (LLMs) handle complex, specialized knowledge remains a critical challenge. We address this through the lens of climate change by introducing CLINB, a benchmark that assesses models on open-ended, grounded, multimodal question answering tasks with clear requirements for knowledge quality and evidential support. CLINB relies on a dataset of real users' questions and evaluation rubrics curated by leading climate scientists. We implement and validate a model-based evaluation process and evaluate several frontier models. Our findings reveal a critical dichotomy. Frontier models demonstrate remarkable knowledge synthesis capabilities, often exhibiting PhD-level understanding and presentation quality. They outperform "hybrid" answers curated by domain experts assisted by weaker models. However, this performance is countered by failures in grounding. The quality of evidence varies, with substantial hallucination rates for references and images. We argue that bridging this gap between knowledge synthesis and verifiable attribution is essential for the deployment of AI in scientific workflows and that reliable, interpretable benchmarks like CLINB are needed to progress towards building trustworthy AI systems.

MiniGPT-Pancreas: Multimodal Large Language Model for Pancreas Cancer Classification and Detection

arXiv:2412.15925v1 Announce Type: cross Abstract: Problem: Pancreas radiological imaging is challenging due to the small size, blurred boundaries, and variability of shape and position of the organ among patients. Goal: In this work we present MiniGPT-Pancreas, a Multimodal Large Language Model (MLLM), as an interactive chatbot to support clinicians in pancreas cancer diagnosis by integrating visual and textual information. Methods: MiniGPT-v2, a general-purpose MLLM, was fine-tuned in a cascaded way for pancreas detection, tumor classification, and tumor detection with multimodal prompts combining questions and computed tomography scans from the National Institute of Health (NIH), and Medical Segmentation Decathlon (MSD) datasets. The AbdomenCT-1k dataset was used to detect the liver, spleen, kidney, and pancreas. Results: MiniGPT-Pancreas achieved an Intersection over Union (IoU) of 0.595 and 0.550 for the detection of pancreas on NIH and MSD datasets, respectively. For the pancreas cancer classification task on the MSD dataset, accuracy, precision, and recall were 0.876, 0.874, and 0.878, respectively. When evaluating MiniGPT-Pancreas on the AbdomenCT-1k dataset for multi-organ detection, the IoU was 0.8399 for the liver, 0.722 for the kidney, 0.705 for the spleen, and 0.497 for the pancreas. For the pancreas tumor detection task, the IoU score was 0.168 on the MSD dataset. Conclusions: MiniGPT-Pancreas represents a promising solution to support clinicians in the classification of pancreas images with pancreas tumors. Future research is needed to improve the score on the detection task, especially for pancreas tumors.

Embedding Explainable AI in NHS Clinical Safety: The Explainability-Enabled Clinical Safety Framework (ECSF)

arXiv:2511.11590v1 Announce Type: cross Abstract: Artificial intelligence (AI) is increasingly embedded in NHS workflows, but its probabilistic and adaptive behaviour conflicts with the deterministic assumptions underpinning existing clinical-safety standards. DCB0129 and DCB0160 provide strong governance for conventional software yet do not define how AI-specific transparency, interpretability, or model drift should be evidenced within Safety Cases, Hazard Logs, or post-market monitoring. This paper proposes an Explainability-Enabled Clinical Safety Framework (ECSF) that integrates explainability into the DCB0129/0160 lifecycle, enabling Clinical Safety Officers to use interpretability outputs as structured safety evidence without altering compliance pathways. A cross-regulatory synthesis mapped DCB clauses to principles from Good Machine Learning Practice, the NHS AI Assurance and T.E.S.T. frameworks, and the EU AI Act. The resulting matrix links regulatory clauses, principles, ECSF checkpoints, and suitable explainability outputs. ECSF introduces five checkpoints: global transparency for hazard identification, case-level interpretability for verification, clinician usability for evaluation, traceable decision pathways for risk control, and longitudinal interpretability monitoring for post-market surveillance. Techniques such as SHAP, LIME, Integrated Gradients, saliency mapping, and attention visualisation are mapped to corresponding DCB artefacts. ECSF reframes explainability as a core element of clinical-safety assurance, bridging deterministic risk governance with the probabilistic behaviour of AI and supporting alignment with GMLP, the EU AI Act, and NHS AI Assurance principles.

A Novel Hierarchical Integration Method for Efficient Model Merging in Medical LLMs

arXiv:2511.13373v1 Announce Type: cross Abstract: Large Language Models (LLMs) face significant challenges in distributed healthcare, including consolidating specialized domain knowledge across institutions while maintaining privacy, reducing computational overhead, and preventing catastrophic forgetting during model updates.This paper presents a systematic evaluation of six parameter-space merging techniques applied to two architecturally compatible medical LLMs derived from the Mistral-7B base model. We introduce a novel hierarchical method that combines selective Optimal Transport (OT) alignment for attention layers with cosine similarity-weighted interpolation, designed to address permutation variance while minimizing computational overhead for edge deployment scenarios. Our study evaluates Task Arithmetic, Linear Averaging, DARE-TIES, DELLA, Breadcrumbs, and our Hierarchical approach across five medical benchmarks. Results demonstrate that architecturally compatible models benefit significantly from simple averaging methods, with Task Arithmetic achieving 45.80% accuracy on MedQA, outperforming complex pruning-based approaches. These findings offer critical insights for the deployment of distributed medical AI in resource-constrained IoT environments, where computational efficiency and model compatibility are paramount. Our work establishes that for architecturally compatible models, simple averaging provides a robust and computationally efficient baseline for knowledge consolidation, offering a pragmatic path forward for scalable medical AI systems.

AI Fairness Beyond Complete Demographics: Current Achievements and Future Directions

arXiv:2511.13525v1 Announce Type: cross Abstract: Fairness in artificial intelligence (AI) has become a growing concern due to discriminatory outcomes in AI-based decision-making systems. While various methods have been proposed to mitigate bias, most rely on complete demographic information, an assumption often impractical due to legal constraints and the risk of reinforcing discrimination. This survey examines fairness in AI when demographics are incomplete, addressing the gap between traditional approaches and real-world challenges. We introduce a novel taxonomy of fairness notions in this setting, clarifying their relationships and distinctions. Additionally, we summarize existing techniques that promote fairness beyond complete demographics and highlight open research questions to encourage further progress in the field.

A large language model-based approach to quantifying the effects of social determinants in liver transplant decisions

npj Digital Medicine, Published online: 17 November 2025; doi:10.1038/s41746-025-02025-y

A large language model-based approach to quantifying the effects of social determinants in liver transplant decisions

Methods for Analytical Validation of Novel Digital Clinical Measures: Implementation Feasibility Evaluation Using Real-World Datasets

Background: Sensor-based digital health technologies (sDHTs) are increasingly used to support scientific and clinical decision-making. The digital measures (DMs) they generate offer significant potential to accelerate the drug development timeline, decrease clinical trial costs, and improve access to care. However, choosing appropriate statistical methodology when conducting analytical validation (AV) of a DM is complicated, particularly for novel DMs, for which appropriate, established reference measures may not exist. More understanding of, and a standardization of approach to, AV in these scenarios is needed. Objective: In a prior simulation study, three statistical methods were tested for their ability to estimate a simulated relationship between a sDHT-derived DM and several clinical outcome assessment (COA) reference measures. The aim of this work was to assess the feasibility of these methods’ implementation in real data, and to examine the impact of AV study design factors on the relationships estimated. Methods: Four real-world datasets, captured using sDHTs, were used to prepare hypothetical AV studies that represented a range of scenarios with respect to three key study design properties: temporal coherence, construct coherence and data completeness. For each hypothetical study, two-factor, correlated-factors confirmatory factor analysis (CFA) models, and a combination of simple and multiple linear regression models, were built using the DM and reference measure data. The factor correlation, R2 and adjusted R2 statistics were calculated, in addition to the Pearson Correlation Coefficients (PCCs). Results: The majority of CFA models exhibited an acceptable fit according to the majority of the fit statistics employed, and each model was able to estimate a factor correlation. For each model, these correlations were greater than or equal to the corresponding PCC in magnitude. Correlations were strongest in the hypothetical studies with strong temporal and construct coherence. Conclusions: The performance of the measures shown in this work supports the feasibility of the selected statistical methods when implemented in real-world data. Our findings in particular support the use of CFA to assess the relationship between a novel digital measure and a COA reference measure. The observed impact of AV study design factors on the relationships estimated allowed the authors to determine practical recommendations to aid in appropriate study design for AV of novel digital measures. By utilizing a standardized methodology for evaluating novel digital measures, sDHT developers, biostatisticians and clinical researchers will be able to navigate the complex validation landscape more easily, with more certainty, and with more tools at their disposal, expediting the pathway to validation and regulatory review.

Case Study: Transformer-Based Solution for the Automatic Digitization of Gas Plants

arXiv:2511.08609v1 Announce Type: cross Abstract: The energy transition is a key theme of the last decades to determine a future of eco-sustainability, and an area of such importance cannot disregard digitization, innovation and the new technological tools available. This is the context in which the Generative Artificial Intelligence models described in this paper are positioned, developed by Engineering Ingegneria Informatica SpA in order to automate the plant structures acquisition of SNAM energy infrastructure, a leading gas transportation company in Italy and Europe. The digitization of a gas plant consists in registering all its relevant information through the interpretation of the related documentation. The aim of this work is therefore to design an effective solution based on Artificial Intelligence techniques to automate the extraction of the information necessary for the digitization of a plant, in order to streamline the daily work of MGM users. The solution received the P&ID of the plant as input, each one in pdf format, and uses OCR, Vision LLM, Object Detection, Relational Reasoning and optimization algorithms to return an output consisting of two sets of information: a structured overview of the relevant design data and the hierarchical framework of the plant. To achieve convincing results, we extend a state-of-the-art model for Scene Graph Generation introducing a brand new Transformer architecture with the aim of deepening the analysis of the complex relations between the plant's components. The synergistic use of the listed AI-based technologies allowed to overcome many obstacles arising from the high variety of data, due to the lack of standardization. An accuracy of 91\% has been achieved in the extraction of textual information relating to design data. Regarding the plants topology, 93\% of components are correctly identified and the hierarchical structure is extracted with an accuracy around 80\%.

Benevolent Dictators? On LLM Agent Behavior in Dictator Games

arXiv:2511.08721v1 Announce Type: cross Abstract: In behavioral sciences, experiments such as the ultimatum game are conducted to assess preferences for fairness or self-interest of study participants. In the dictator game, a simplified version of the ultimatum game where only one of two players makes a single decision, the dictator unilaterally decides how to split a fixed sum of money between themselves and the other player. Although recent studies have explored behavioral patterns of AI agents based on Large Language Models (LLMs) instructed to adopt different personas, we question the robustness of these results. In particular, many of these studies overlook the role of the system prompt - the underlying instructions that shape the model's behavior - and do not account for how sensitive results can be to slight changes in prompts. However, a robust baseline is essential when studying highly complex behavioral aspects of LLMs. To overcome previous limitations, we propose the LLM agent behavior study (LLM-ABS) framework to (i) explore how different system prompts influence model behavior, (ii) get more reliable insights into agent preferences by using neutral prompt variations, and (iii) analyze linguistic features in responses to open-ended instructions by LLM agents to better understand the reasoning behind their behavior. We found that agents often exhibit a strong preference for fairness, as well as a significant impact of the system prompt on their behavior. From a linguistic perspective, we identify that models express their responses differently. Although prompt sensitivity remains a persistent challenge, our proposed framework demonstrates a robust foundation for LLM agent behavior studies. Our code artifacts are available at https://github.com/andreaseinwiller/LLM-ABS.

AgentFlux: Decoupled Fine-Tuning & Inference for On-Device Agentic Systems

arXiv:2510.00229v4 Announce Type: replace Abstract: The deployment of Large Language Models (LLMs) as agentic orchestrators has revolutionized task automation, but the need for privacy-preserving, cost-effective solutions demands on-device inference capabilities. However, local LLMs consistently underperform compared to frontier models in tool calling scenarios, struggling with both tool selection from large tool sets and accurate argument generation for complex parameter structures. We introduce a methodology that disaggregates a tool-calling task into two distinct subtasks: tool selection and argument generation. We propose "decoupled fine-tuning", a novel post-training approach that employs LoRA fine-tuning to create dedicated LoRA adapters for tool selection and tool-specific argument generation using separate loss masking for each of the subtasks. Furthermore, we present AgentFlux, an inference framework that leverages the LoRA adapters created using decoupled fine-tuning to perform efficient agent orchestration with the help of local models on end-user devices. AgentFlux decomposes the tool-call generation step into tool selection and argument generation, and dynamically loads the corresponding LoRA adapters to generate tool calls. Additionally, AgentFlux implements hierarchical orchestration to restrict the number of tools required for tool selection. Our experiments on the MCP-Bench benchmark demonstrate that the Qwen-2.5-7B model trained using decoupled fine-tuning improves the tool calling accuracy of the base model by 46%, and outperforms other local reasoning, non-reasoning and fine-tuned models of similar size in all cases, and models that are 2x larger, in most cases.

LLM4AD: Large Language Models for Autonomous Driving - Concept, Review, Benchmark, Experiments, and Future Trends

arXiv:2410.15281v4 Announce Type: replace-cross Abstract: With the broader adoption and highly successful development of Large Language Models (LLMs), there has been growing interest and demand for applying LLMs to autonomous driving technology. Driven by their natural language understanding and reasoning capabilities, LLMs have the potential to enhance various aspects of autonomous driving systems, from perception and scene understanding to interactive decision-making. In this paper, we first introduce the novel concept of designing Large Language Models for Autonomous Driving (LLM4AD), followed by a review of existing LLM4AD studies. Then, we propose a comprehensive benchmark for evaluating the instruction-following and reasoning abilities of LLM4AD systems, which includes LaMPilot-Bench, CARLA Leaderboard 1.0 Benchmark in simulation and NuPlanQA for multi-view visual question answering. Furthermore, we conduct extensive real-world experiments on autonomous vehicle platforms, examining both on-cloud and on-edge LLM deployment for personalized decision-making and motion control. Next, we explore the future trends of integrating language diffusion models into autonomous driving, exemplified by the proposed ViLaD (Vision-Language Diffusion) framework. Finally, we discuss the main challenges of LLM4AD, including latency, deployment, security and privacy, safety, trust and transparency, and personalization.

Asking the Right Questions: Benchmarking Large Language Models in the Development of Clinical Consultation Templates

arXiv:2508.01159v2 Announce Type: replace-cross Abstract: This study evaluates the capacity of large language models (LLMs) to generate structured clinical consultation templates for electronic consultation. Using 145 expert-crafted templates developed and routinely used by Stanford's eConsult team, we assess frontier models -- including o3, GPT-4o, Kimi K2, Claude 4 Sonnet, Llama 3 70B, and Gemini 2.5 Pro -- for their ability to produce clinically coherent, concise, and prioritized clinical question schemas. Through a multi-agent pipeline combining prompt optimization, semantic autograding, and prioritization analysis, we show that while models like o3 achieve high comprehensiveness (up to 92.2\%), they consistently generate excessively long templates and fail to correctly prioritize the most clinically important questions under length constraints. Performance varies across specialties, with significant degradation in narrative-driven fields such as psychiatry and pain medicine. Our findings demonstrate that LLMs can enhance structured clinical information exchange between physicians, while highlighting the need for more robust evaluation methods that capture a model's ability to prioritize clinically salient information within the time constraints of real-world physician communication.

Early Detection of Lung Cancer: A Review of Innovative Milestones and Techniques

J Clin Med. 2025 Nov 3;14(21):7812. doi: 10.3390/jcm14217812.

ABSTRACT

Lung cancer is the most frequently diagnosed cancer and the leading cause of cancer death worldwide. Early detection of lung cancer can lead to identification of the cancer at its initial treatable stages and improves survival. Low-dose CT scan (LDCT) is currently the gold standard for lung cancer screening in high-risk individuals. Despite the observed stage migration and consistently demonstrated disease-specific overall survival benefit, LDCT has inherent limitations, including false-positive results, radiation exposure, and low compliance. Recently, new techniques have been investigated for early detection of lung cancer. Several studies have shown that liquid biopsy biomarkers such as circulating cell-free DNA (cfDNA), microRNA molecules (miRNA), circulating tumor cells (CTCs), tumor-derived exosomes (TDEs), and tumor-educated platelets (TEPs), as well as volatile organic compounds (VOCs), have the power to distinguish lung cancer patients from healthy subjects, offering potential for minimally invasive and non-invasive means of early cancer detection. Furthermore, recent studies have shown that the integration of artificial intelligence (AI) with clinical, imaging, and laboratory data has provided significant advancements and can offer potential solutions to some challenges related to early detection of lung cancer. Adopting AI-based multimodality strategies, such as multi-omics liquid biopsy and/or VOCs' detection, with LDCT augmented by advanced AI, could revolutionize early lung cancer screening by improving accuracy, efficiency, and personalization, especially when combined with patient clinical data. However, challenges remain in validating, standardizing, and integrating these approaches into clinical practice. In this review, we described these innovative milestones and methods, as well as their advantages and limitations in screening and early diagnosis of lung cancer.

PMID:41227214 | PMC:PMC12609116 | DOI:10.3390/jcm14217812

❌