❌

Normal view

  • ✇MIT Technology Review
  • The Download: gig workers training humanoids, and better AI benchmarks Thomas Macaulay
    This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. The gig workers who are training humanoid robots at home  When Zeus, a medical student in Nigeria, returns to his apartment from a long day at the hospital, he straps his iPhone to his forehead and records himself doing chores.  Zeus is a data recorder for Micro1, which sells the data he collects to robotics firms. As these companies race to build hum
     

The Download: gig workers training humanoids, and better AI benchmarks

1 April 2026 at 20:10

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology.

The gig workers who are training humanoid robots at home 

When Zeus, a medical student in Nigeria, returns to his apartment from a long day at the hospital, he straps his iPhone to his forehead and records himself doing chores. 

Zeus is a data recorder for Micro1, which sells the data he collects to robotics firms. As these companies race to build humanoids, videos from workers like Zeus have become the hottest new way to train them.  

Micro1 has hired thousands of them in more than 50 countries, including India, Nigeria, and Argentina. The jobs pay well locally, but raise thorny questions around privacy and informed consent. The work can be challenging—and weird. Read the full story. 

—Michelle Kim 

Our readers recently voted humanoid robots the “11th breakthrough” to add to our 2026 list of 10 Breakthrough Technologies. Check out what else officially made the cut. 

AI benchmarks are broken. Here’s what we need instead. 

For decades, AI has been evaluated based on whether it can outperform humans on isolated problems. But it’s seldom used this way in the real world. 

While AI is assessed in a vacuum, it operates in messy, complex, multi-person environments over time. This misalignment leads us to misunderstand its capabilities, risks, and impacts. 

We need new benchmarks that assess AI’s performance over longer horizons within human teams, workflows, and organizations. Here’s a proposal for one such approach: Human–AI, Context-Specific Evaluation.  

—Angela Aristidou, professor at University College London and faculty fellow at the Stanford Digital Economy Lab and the Stanford Human-Centered AI Institute. 

MIT Technology Review Narrated: can quantum computers now solve health care problems? We’ll soon find out. 

In a laboratory on the outskirts of Oxford, a quantum computer built from atoms and light awaits its moment. The device is small but powerful—and also very valuable. Infleqtion, the company that owns it, is hoping its abilities will win $5 million at a competition.  

The prize will go to the quantum computer that can solve real health care problems that “classical” computers cannot. But there can be only one big winner—if there is a winner at all. 

—Michael Brooks 

This is our latest story to be turned into an MIT Technology Review Narrated podcast, which we’re publishing each week on Spotify and Apple Podcasts. Just navigate to MIT Technology Review Narrated on either platform, and follow us to get all our new content as it’s released. 

The must-reads 

I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 

1 OpenAI just closed the biggest funding round in Silicon Valley history 
It raised $122 billion ahead of its blockbuster IPO, which is expected later this year. (WSJ $) 
+ It’s also prepping a push to “rethink the social contract.” (Vanity Fair $) 
+ Campaigners are urging people to quit ChatGPT. (MIT Technology Review)   

2 Iran has threatened to attack 18 US tech companies  
It’s eyeing their operations in the Middle East. (Politico) 
+ Targets include Nvidia, Apple, Microsoft, and Google. (Engadget) 
+ Iran struck AWS data centers earlier this month. (Reuters $) 

3 Artemis II is about to fly humans to the Moon. Here’s the science they’ll do 
Their experiments will set the stage for future explorers. (Nature) 
+ You can watch the launch attempt today. (Engadget)  

4 Putin is trying to take full control of Russia’s internet 
New outages and blockages are cutting the country off from the world. (NYT $) 
+ Can we repair the internet? (MIT Technology Review) 

5 A robotaxi outage in China left passengers stranded on highways  
Baidu vehicles froze on the streets of Wuhan. (Bloomberg $) 
+ Police are blaming a “system failure.” (Reuters $) 

6 US government requests for social media user data are soaring 
They’ve skyrocketed by 770% in the past decade. (Bloomberg $) 
+ Is the Pentagon allowed to surveil Americans with AI? (MIT Technology Review) 

7 Tesla has admitted that humans sometimes drive its robotaxis 
Remote drivers occasionally control them completely. (Wired $) 

8 A satellite-smashing chain reaction could spiral out of control 
This data visualization captures the dangers of space collisions. (Guardian) 
+ Here’s all the stuff we’ve put into space. (MIT Technology Review) 

9 Meta’s smartglasses can turn you into a creep 
According to one journalist who wore them for a month. (Guardian) 

10 A Claude Code leak has exposed plans for a virtual pet  
We could be getting a Tamagotchi for the GenAI era. (The Verge) 

Quote of the day 

“From now on, for every assassination, an American company will be destroyed.” 

—Iran’s Islamic Revolutionary Guard Corps (IRGC) threatens US tech firms in an affiliated Telegram, per CNBC. 

One More Thing 

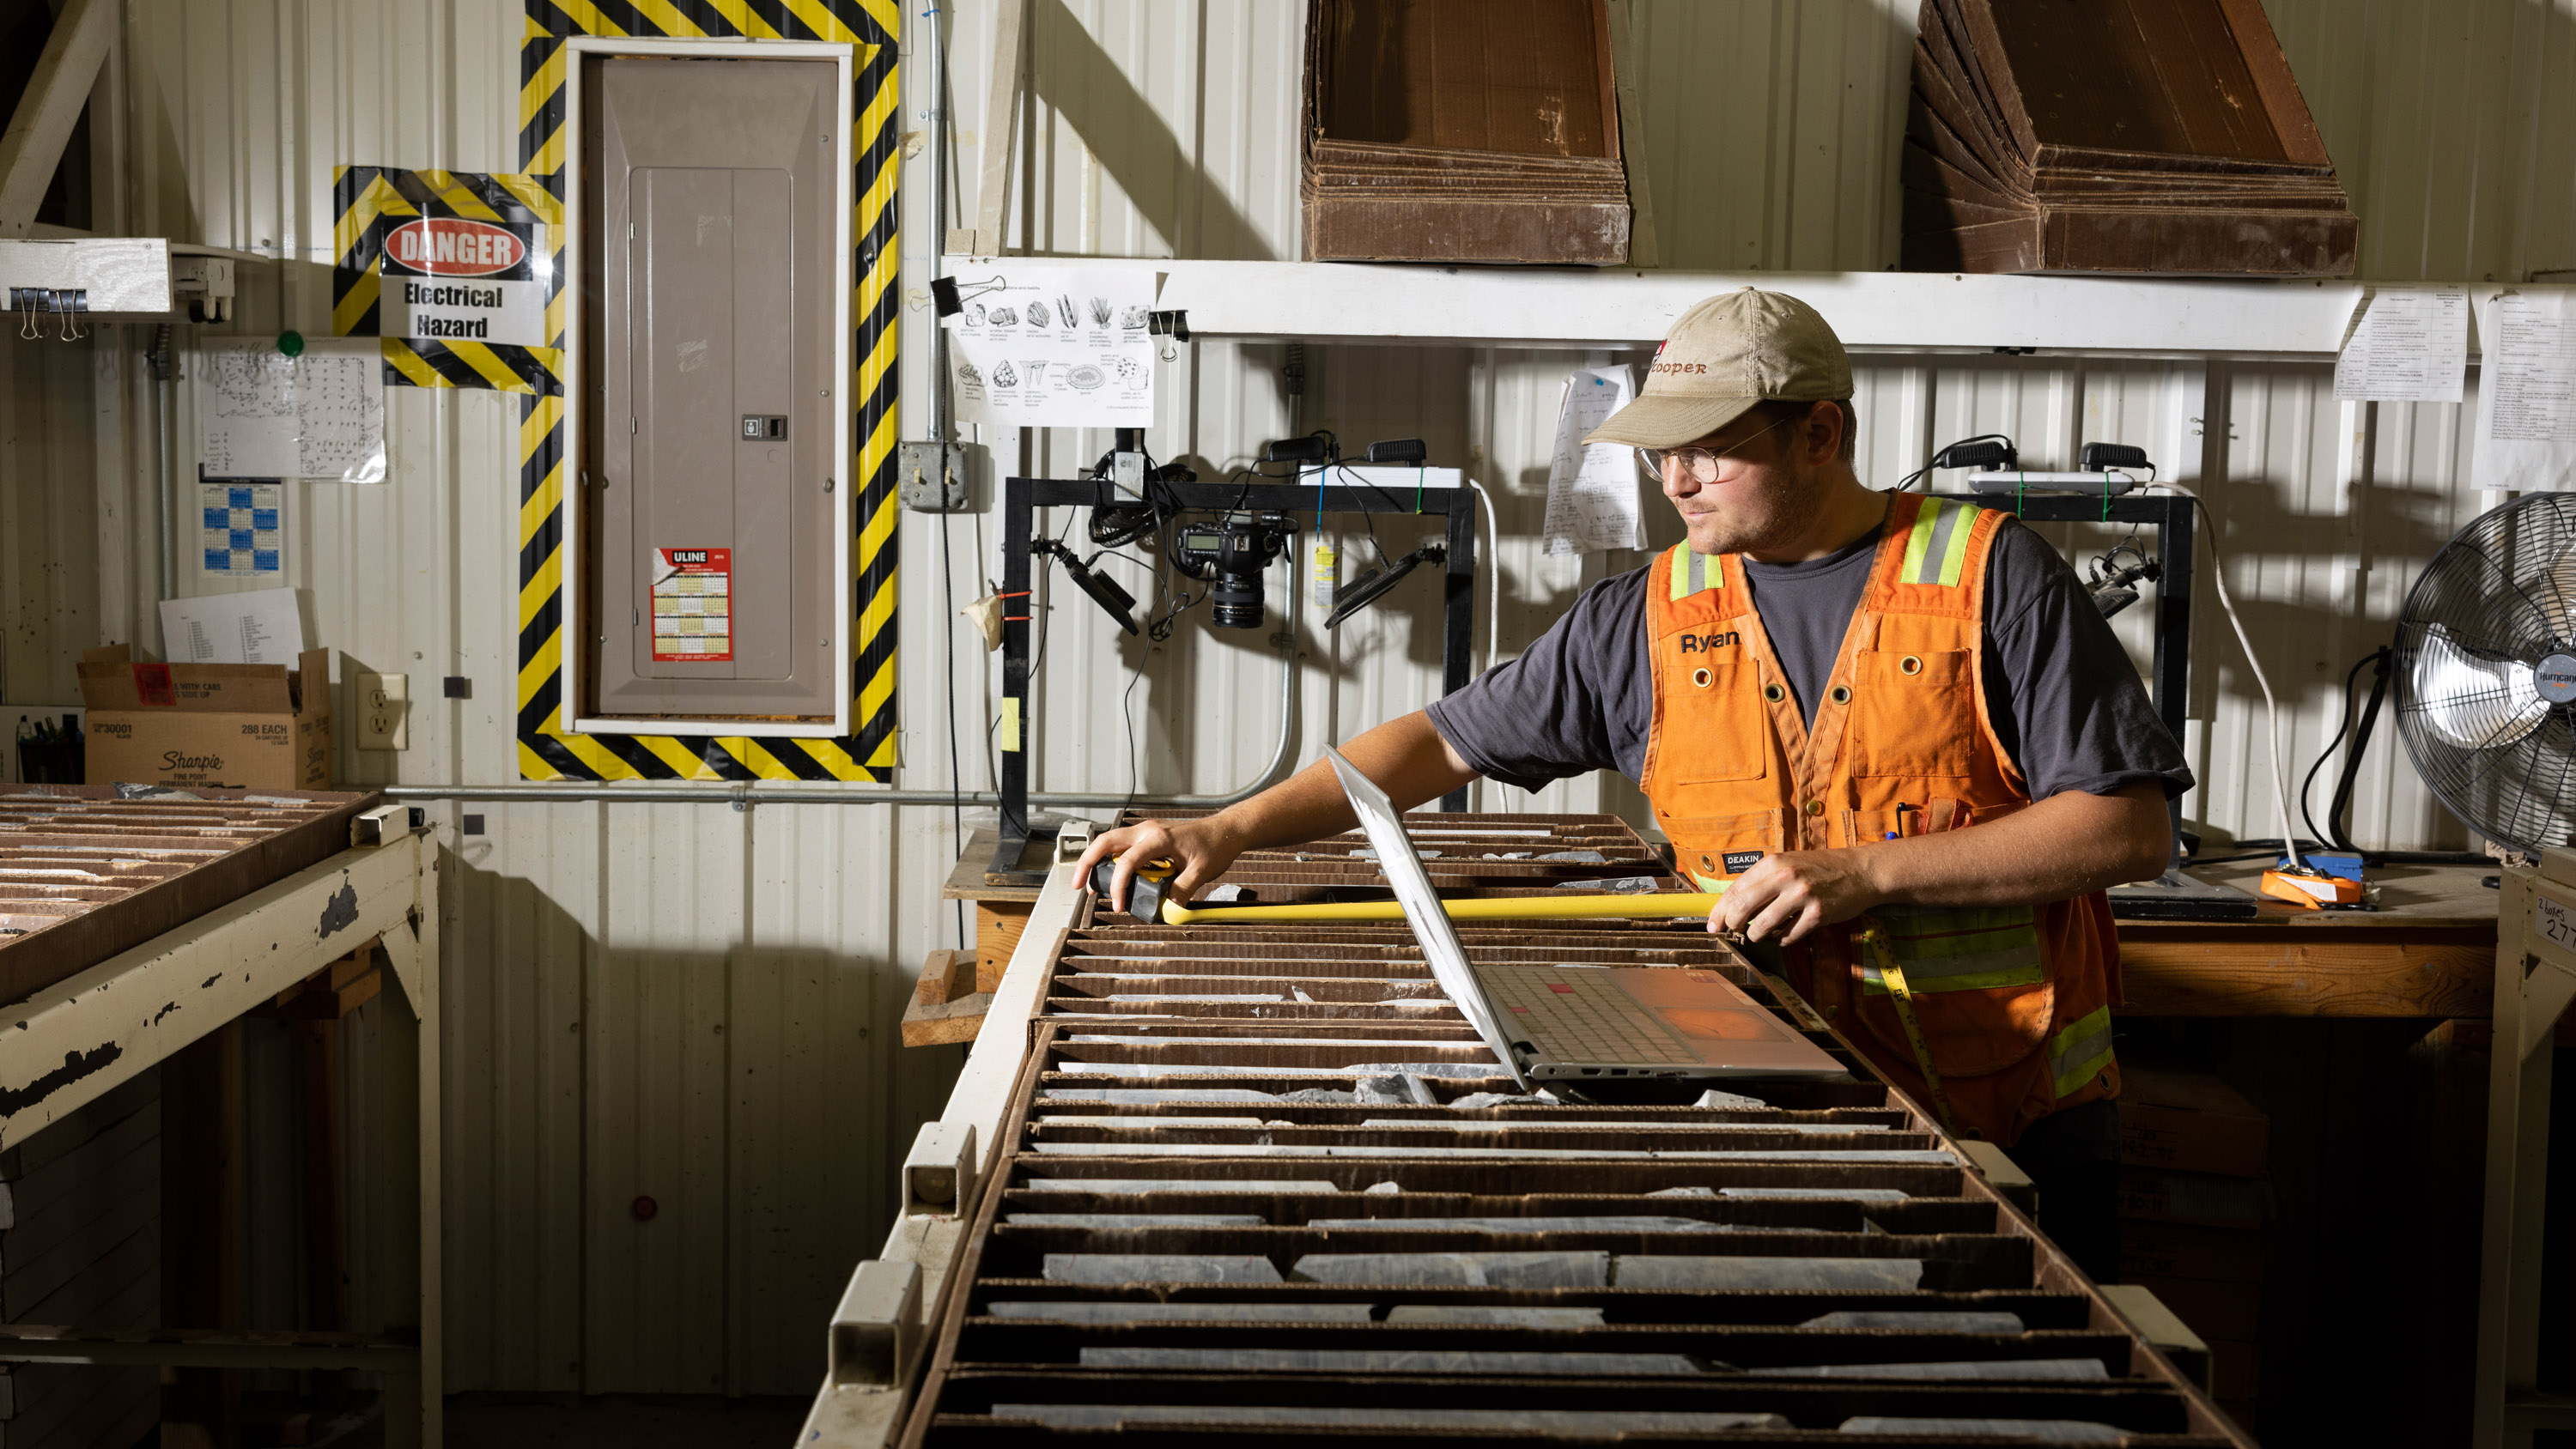
Ryan Willgosh of Talon Metals logs samples
ACKERMAN + GRUBER

How one mine could unlock billions in EV subsidies 

In a pine farm north of the tiny town of Tamarack, Minnesota, Talon Metals has uncovered one of America’s densest nickel deposits. Now it wants to begin mining the ore. 

Products made from the nickel could net more than $26 billion in subsidies through the Inflation Reduction Act (IRA), which is starting to transform the US economy. To understand how, we tallied up the potential tax credits available. Read the full story to find out what we discovered. 

—James Temple 

We can still have nice things 

A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.) 

+ A selfless group of gluttons tried to taste-test every potato chip in the world.  
+ Get romantic inspiration from these penguins’ engagement pebbles. 
+ Good news: global terrorism has hit a 15-year low. 
+ Enjoy endless new views through these windows around the world.  

  • ✇cs.AI, q-bio.NC updates on arXiv.org
  • The Future of AI is Many, Not One Daniel J. Singer · Luca Garzino Demo
    arXiv:2603.29075v1 Announce Type: new Abstract: The way we're thinking about generative AI right now is fundamentally individual. We see this not just in how users interact with models but also in how models are built, how they're benchmarked, and how commercial and research strategies using AI are defined. We argue that we should abandon this approach if we're hoping for AI to support groundbreaking innovation and scientific discovery. Drawing on research and formal results in complex systems,
     

The Future of AI is Many, Not One

arXiv:2603.29075v1 Announce Type: new Abstract: The way we're thinking about generative AI right now is fundamentally individual. We see this not just in how users interact with models but also in how models are built, how they're benchmarked, and how commercial and research strategies using AI are defined. We argue that we should abandon this approach if we're hoping for AI to support groundbreaking innovation and scientific discovery. Drawing on research and formal results in complex systems, organizational behavior, and philosophy of science, we show why we should expect deep intellectual breakthroughs to come from epistemically diverse groups of AI agents working together rather than singular superintelligent agents. Having a diverse team broadens the search for solutions, delays premature consensus, and allows for the pursuit of unconventional approaches. Developing diverse AI teams also addresses AI critics' concerns that current models are constrained by past data and lack the creative insight required for innovation. The upshot, we argue, is that the future of transformative transformer-based AI is fundamentally many, not one.

Knowledge database development by large language models for countermeasures against viruses and marine toxins

arXiv:2603.29149v1 Announce Type: new Abstract: Access to the most up-to-date information on medical countermeasures is important for the research and development of effective treatments for viruses and marine toxins. However, there is a lack of comprehensive databases that curate data on viruses and marine toxins, making decisions on medical countermeasures slow and difficult. In this work, we employ two large language models (LLMs) of ChatGPT and Grok to design two comprehensive databases of therapeutic countermeasures for five viruses of Lassa, Marburg, Ebola, Nipah, and Venezuelan equine encephalitis, as well as marine toxins. With high-level human-provided inputs, the two LLMs identify public databases containing data on the five viruses and marine toxins, collect relevant information from these databases and the literature, iteratively cross-validate the collected information, and design interactive webpages for easy access to the curated, comprehensive databases. Notably, the ChatGPT LLM is employed to design agentic AI workflows (consisting of two AI agents for research and decision-making) to rank countermeasures for viruses and marine toxins in the databases. Together, our work explores the potential of LLMs as a scalable, updatable approach for building comprehensive knowledge databases and supporting evidence-based decision-making.

Optimizing Donor Outreach for Blood Collection Sessions: A Scalable Decision Support Framework

arXiv:2603.29643v1 Announce Type: new Abstract: Blood donation centers face challenges in matching supply with demand while managing donor availability. Although targeted outreach is important, it can cause donor fatigue via over-solicitation. Effective recruitment requires targeting the right donors at the right time, balancing constraints with donor convenience and eligibility. Despite extensive work on blood supply chain optimization and growing interest in algorithmic donor recruitment, the operational problem of assigning donors to sessions across a multi-site network, taking into account eligibility, capacity, blood-type demand targets, geographic convenience, and donor safety, remains unaddressed. We address this gap with an optimization framework for donor invitation scheduling incorporating donor eligibility, travel convenience, blood-type demand targets, and penalties. We evaluate two strategies: (i) a binary integer linear programming (BILP) formulation and (ii) an efficient greedy heuristic. Evaluation uses the registry from Instituto Portugu\^es do Sangue e da Transplanta\c{c}\~ao (IPST) for invite planning in the Lisbon operational region using 4-month windows. A prospective pipeline integrates organic attendance forecasting, quantile-based demand targets, and residual capacity estimation for forward-looking invitation plans. Results reveal its key role in closing the supply-demand gap in the Lisbon operational region. A controlled comparison shows that the greedy heuristic achieves results comparable to the BILP, with 188x less peak memory and 115x faster runtime; trade-offs include 3.9 pp lower demand fulfillment (86.1% vs. 90.0%), larger donor-session distance, higher adverse-reaction donor exposure, and greater invitation burden per non-high-frequency donor, reflecting local versus global optimization. Experiments assess how constraint-aware scheduling can close gaps by mobilizing eligible inactive/lapsing donors.

ScoringBench: A Benchmark for Evaluating Tabular Foundation Models with Proper Scoring Rules

arXiv:2603.29928v1 Announce Type: new Abstract: Tabular foundation models such as TabPFN and TabICL already produce full predictive distributions yet prevailing regression benchmarks evaluate them almost exclusively via point estimate metrics RMSE R2 These aggregate measures often obscure model performance in the tails of the distribution a critical deficit for high stakes decision making in domains like finance and clinical research where asymmetric risk profiles are the norm We introduce ScoringBench an open benchmark that computes a comprehensive suite of proper scoring rules like CRPS CRLS Interval Score Energy Score weighted CRPS and Brier Score alongside standard point metrics providing a richer picture of probabilistic forecast quality We evaluate realTabPFNv2.5 fine tuned with different scoring rule objectives and TabICL relative to untuned realTabPFNv2.5 across a suite of regression benchmarks Our results confirm that model rankings depend on the chosen scoring rule and that no single pretraining objective is universally optimal This demonstrates that for applications sensitive to extreme events the choice of evaluation metric is as much a domain specific requirement as the data itself ScoringBench is available at https://github.com/jonaslandsgesell/ScoringBench A live preview of the current leaderboard is available at https://scoringbench.bolt.host The leaderboard is maintained via git pull requests to ensure transparency traceability agility and reproducibility

From Patterns to Policy: A Scoping Review Based on Bibliometric Analysis (ScoRBA) of Intelligent and Secure Smart Hospital Ecosystems

arXiv:2603.30004v1 Announce Type: new Abstract: This study examines the evolution of Intelligent and Secure Smart Hospital Ecosystems using a Scoping Review with Bibliometric Analysis (ScoRBA) to map research patterns, identify gaps, and derive policy implications. Analyzing 891 journal articles from Scopus (2006-2025) through co-occurrence analysis, network visualization, overlay analysis, and the Enhanced Strategic Diagram (ESD), the study applies the PAGER framework to link Patterns, Advances, Gaps, Research directions, and Evidence-based policy implications. Findings reveal three interrelated clusters: AI-driven intelligent healthcare systems, decentralized privacy-preserving digital health ecosystems, and scalable cloud-edge infrastructures, showing a convergence toward integrated ecosystem architectures where intelligence, trust, and infrastructure reinforce each other. Despite progress in AI, blockchain, and cloud computing, gaps remain in interoperability, real-world implementation, governance, and cross-layer integration. Emerging themes such as explainable AI, federated learning, and privacy mechanisms highlight areas needing further research. Policy-relevant recommendations focus on coordinated governance, scalable infrastructure, and secure data ecosystems, particularly for developing country contexts. The study bridges bibliometric evidence with actionable policies, supporting informed decision-making in smart hospital development.

Focus360: Guiding User Attention in Immersive Videos for VR

arXiv:2603.28774v1 Announce Type: cross Abstract: This demo introduces Focus360, a system designed to enhance user engagement in 360{\deg} VR videos by guiding attention to key elements within the scene. Using natural language descriptions, the system identifies important elements and applies a combination of visual effects to guide attention seamlessly. At the demonstration venue, participants can experience a 360{\deg} Safari Tour, showcasing the system's ability to improve user focus while maintaining an immersive experience.

AI in Work-Based Learning: Understanding the Purposes and Effects of Intelligent Tools Among Student Interns

arXiv:2603.28786v1 Announce Type: cross Abstract: This study examined how student interns in Philippine higher education use intelligent tools during their OJT. Data were collected from 384 respondents using a structured questionnaire that asked about AI tool usage, task-specific applications, and perceptions of confidence, ethics, and support. Analysis of task-based usage identified four main purposes: productivity and report writing, communication and content drafting, technical assistance and code support, and independent task completion. ChatGPT was the most commonly used AI tool, followed by Quillbot, Canva AI, and Grammarly. Students reported moderate confidence in using AI and applied these tools selectively and ethically during OJT tasks. This indicate that AI tools assist student interns in various OJT activities related to work-readiness. The study suggests that higher education programs include AI literacy and onboarding. Clear policies and fair access to AI tools are important to support responsible use and prepare students for future careers.

GaloisSAT: Differentiable Boolean Satisfiability Solving via Finite Field Algebra

arXiv:2603.28796v1 Announce Type: cross Abstract: Boolean satisfiability (SAT) problem, the first problem proven to be NP-complete, has become a fundamental challenge in computational complexity, with widespread applications in optimization and verification across many domains. Despite significant algorithmic advances over the past two decades, the performance of SAT solvers has improved at a limited pace. Notably, the 2025 competition winner shows only about a 2X improvement over the 2006 winner in SAT Competition performance after nearly 20 years of effort. This paper introduces GaloisSAT, a novel hybrid GPU-CPU SAT solver that integrates a differentiable SAT solving engine powered by modern machine learning infrastructure on GPUs, followed by a traditional CDCL-based SAT solving stage on CPUs. GaloisSAT is benchmarked against the latest versions of state-of-the-art solvers, Kissat and CaDiCaL, using the SAT Competition 2024 benchmark suite. Results demonstrate substantial improvements in the official SAT Competition metric PAR-2 (penalized average runtime with a timeout of 5,000 seconds and a penalty factor of 2). Specifically, GaloisSAT achieves an 8.41X speedup in the satisfiable category and a 1.29X speedup in the unsatisfiable category compared to the strongest baselines.

OccSim: Multi-kilometer Simulation with Long-horizon Occupancy World Models

arXiv:2603.28887v1 Announce Type: cross Abstract: Data-driven autonomous driving simulation has long been constrained by its heavy reliance on pre-recorded driving logs or spatial priors, such as HD maps. This fundamental dependency severely limits scalability, restricting open-ended generation capabilities to the finite scale of existing collected datasets. To break this bottleneck, we present OccSim, the first occupancy world model-driven 3D simulator. OccSim obviates the requirement for continuous logs or HD maps; conditioned only on a single initial frame and a sequence of future ego-actions, it can stably generate over 3,000 continuous frames, enabling the continuous construction of large-scale 3D occupancy maps spanning over 4 kilometers for simulation. This represents an >80x improvement in stable generation length over previous state-of-the-art occupancy world models. OccSim is powered by two modules: W-DiT based static occupancy world model and the Layout Generator. W-DiT handles the ultra-long-horizon generation of static environments by explicitly introducing known rigid transformations in architecture design, while the Layout Generator populates the dynamic foreground with reactive agents based on the synthesized road topology. With these designs, OccSim can synthesize massive, diverse simulation streams. Extensive experiments demonstrate its downstream utility: data collected directly from OccSim can pre-train 4D semantic occupancy forecasting models to achieve up to 67% zero-shot performance on unseen data, outperforming previous asset-based simulator by 11%. When scaling the OccSim dataset to 5x the size, the zero-shot performance increases to about 74%, while the improvement over asset-based simulators expands to 22.1%.

Theory of Mind and Self-Attributions of Mentality are Dissociable in LLMs

arXiv:2603.28925v1 Announce Type: cross Abstract: Safety fine-tuning in Large Language Models (LLMs) seeks to suppress potentially harmful forms of mind-attribution such as models asserting their own consciousness or claiming to experience emotions. We investigate whether suppressing mind-attribution tendencies degrades intimately related socio-cognitive abilities such as Theory of Mind (ToM). Through safety ablation and mechanistic analyses of representational similarity, we demonstrate that LLM attributions of mind to themselves and to technological artefacts are behaviorally and mechanistically dissociable from ToM capabilities. Nevertheless, safety fine-tuned models under-attribute mind to non-human animals relative to human baselines and are less likely to exhibit spiritual belief, suppressing widely shared perspectives regarding the distribution and nature of non-human minds.

Multi-Agent LLMs for Adaptive Acquisition in Bayesian Optimization

arXiv:2603.28959v1 Announce Type: cross Abstract: The exploration-exploitation trade-off is central to sequential decision-making and black-box optimization, yet how Large Language Models (LLMs) reason about and manage this trade-off remains poorly understood. Unlike Bayesian Optimization, where exploration and exploitation are explicitly encoded through acquisition functions, LLM-based optimization relies on implicit, prompt-based reasoning over historical evaluations, making search behavior difficult to analyze or control. In this work, we present a metric-level study of LLM-mediated search policy learning, studying how LLMs construct and adapt exploration-exploitation strategies under multiple operational definitions of exploration, including informativeness, diversity, and representativeness. We show that single-agent LLM approaches, which jointly perform strategy selection and candidate generation within a single prompt, suffer from cognitive overload, leading to unstable search dynamics and premature convergence. To address this limitation, we propose a multi-agent framework that decomposes exploration-exploitation control into strategic policy mediation and tactical candidate generation. A strategy agent assigns interpretable weights to multiple search criteria, while a generation agent produces candidates conditioned on the resulting search policy defined as weights. This decomposition renders exploration-exploitation decisions explicit, observable, and adjustable. Empirical results across various continuous optimization benchmarks indicate that separating strategic control from candidate generation substantially improves the effectiveness of LLM-mediated search.

Design Principles for the Construction of a Benchmark Evaluating Security Operation Capabilities of Multi-agent AI Systems

arXiv:2603.28998v1 Announce Type: cross Abstract: As Large Language Models (LLMs) and multi-agent AI systems are demonstrating increasing potential in cybersecurity operations, organizations, policymakers, model providers, and researchers in the AI and cybersecurity communities are interested in quantifying the capabilities of such AI systems to achieve more autonomous SOCs (security operation centers) and reduce manual effort. In particular, the AI and cybersecurity communities have recently developed several benchmarks for evaluating the red team capabilities of multi-agent AI systems. However, because the operations in SOCs are dominated by blue team operations, the capabilities of AI systems & agents to achieve more autonomous SOCs cannot be evaluated without a benchmark focused on blue team operations. To our best knowledge, no systematic benchmark for evaluating coordinated multi-task blue team AI has been proposed in the literature. Existing blue team benchmarks focus on a particular task. The goal of this work is to develop a set of design principles for the construction of a benchmark, which is denoted as SOC-bench, to evaluate the blue team capabilities of AI. Following these design principles, we have developed a conceptual design of SOC-bench, which consists of a family of five blue team tasks in the context of large-scale ransomware attack incident response.

A Latent Risk-Aware Machine Learning Approach for Predicting Operational Success in Clinical Trials based on TrialsBank

arXiv:2603.29041v1 Announce Type: cross Abstract: Clinical trials are characterized by high costs, extended timelines, and substantial operational risk, yet reliable prospective methods for predicting trial success before initiation remain limited. Existing artificial intelligence approaches often focus on isolated metrics or specific development stages and frequently rely on variables unavailable at the trial design phase, limiting real-world applicability. We present a hierarchical latent risk-aware machine learning framework for prospective prediction of clinical trial operational success using a curated subset of TrialsBank, a proprietary AI-ready database developed by Sorintellis, comprising 13,700 trials. Operational success was defined as the ability to initiate, conduct, and complete a clinical trial according to planned timelines, recruitment targets, and protocol specifications through database lock. This approach decomposes operational success prediction into two modeling stages. First, intermediate latent operational risk factors are predicted using more than 180 drug- and trial-level features available before trial initiation. These predicted latent risks are then integrated into a downstream model to estimate the probability of operational success. A staged data-splitting strategy was employed to prevent information leakage, and models were benchmarked using XGBoost, CatBoost, and Explainable Boosting Machines. Across Phase I-III, the framework achieves strong out-of-sample performance, with F1-scores of 0.93, 0.92, and 0.91, respectively. Incorporating latent risk drivers improves discrimination of operational failures, and performance remains robust under independent inference evaluation. These results demonstrate that clinical trial operational success can be prospectively forecasted using a latent risk-aware AI framework, enabling early risk assessment and supporting data-driven clinical development decision-making.

Evaluating a Data-Driven Redesign Process for Intelligent Tutoring Systems

arXiv:2603.29094v1 Announce Type: cross Abstract: Past research has defined a general process for the data-driven redesign of educational technologies and has shown that in carefully-selected instances, this process can help make systems more effective. In the current work, we test the generality of the approach by applying it to four units of a middle-school mathematics intelligent tutoring system that were selected not based on suitability for redesign, as in previous work, but on topic. We tested whether the redesigned system was more effective than the original in a classroom study with 123 students. Although the learning gains did not differ between the conditions, students who used the Redesigned Tutor had more productive time-on-task, a larger number of skills practiced, and greater total knowledge mastery. The findings highlight the promise of data-driven redesign even when applied to instructional units *not* selected as likely to yield improvement, as evidence of the generality and wide applicability of the method.

Software Vulnerability Detection Using a Lightweight Graph Neural Network

arXiv:2603.29216v1 Announce Type: cross Abstract: Large Language Models (LLMs) have emerged as a popular choice in vulnerability detection studies given their foundational capabilities, open source availability, and variety of models, but have limited scalability due to extensive compute requirements. Using the natural graph relational structure of code, we show that our proposed graph neural network (GNN) based deep learning model VulGNN for vulnerability detection can achieve performance almost on par with LLMs, but is 100 times smaller in size and fast to retrain and customize. We describe the VulGNN architecture, ablation studies on components, learning rates, and generalizability to different code datasets. As a lightweight model for vulnerability analysis, VulGNN is efficient and deployable at the edge as part of real-world software development pipelines.

Hybrid Quantum-Classical Spatiotemporal Forecasting for 3D Cloud Fields

arXiv:2603.29407v1 Announce Type: cross Abstract: Accurate forecasting of three-dimensional (3D) cloud fields is important for atmospheric analysis and short-range numerical weather prediction, yet it remains challenging because cloud evolution involves cross-layer interactions, nonlocal dependencies, and multiscale spatiotemporal dynamics. Existing spatiotemporal prediction models based on convolutions, recurrence, or attention often rely on locality-biased representations and therefore struggle to preserve fine cloud structures in volumetric forecasting tasks. To address this issue, we propose QENO, a hybrid quantum-inspired spatiotemporal forecasting framework for 3D cloud fields. The proposed architecture consists of four components: a classical spatiotemporal encoder for compact latent representation, a topology-aware quantum enhancement block for modeling nonlocal couplings in latent space, a dynamic fusion temporal unit for integrating measurement-derived quantum features with recurrent memory, and a decoder for reconstructing future cloud volumes. Experiments on CMA-MESO 3D cloud fields show that QENO consistently outperforms representative baselines, including ConvLSTM, PredRNN++, Earthformer, TAU, and SimVP variants, in terms of MSE, MAE, RMSE, SSIM, and threshold-based detection metrics. In particular, QENO achieves an MSE of 0.2038, an RMSE of 0.4514, and an SSIM of 0.6291, while also maintaining a compact parameter budget. These results indicate that topology-aware hybrid quantum-classical feature modeling is a promising direction for 3D cloud structure forecasting and atmospheric Earth observation data analysis.

Agenda-based Narrative Extraction: Steering Pathfinding Algorithms with Large Language Models

arXiv:2603.29661v1 Announce Type: cross Abstract: Existing narrative extraction methods face a trade-off between coherence, interactivity, and multi-storyline support. Narrative Maps supports rich interaction and generates multiple storylines as a byproduct of its coverage constraints, though this comes at the cost of individual path coherence. Narrative Trails achieves high coherence through maximum capacity path optimization but provides no mechanism for user guidance or multiple perspectives. We introduce agenda-based narrative extraction, a method that bridges this gap by integrating large language models into the Narrative Trails pathfinding process to steer storyline construction toward user-specified perspectives. Our approach uses an LLM at each step to rank candidate documents based on their alignment with a given agenda while maintaining narrative coherence. Running the algorithm with different agendas yields different storylines through the same corpus. We evaluated our approach on a news article corpus using LLM judges with Claude Opus 4.5 and GPT 5.1, measuring both coherence and agenda alignment across 64 endpoint pairs and 6 agendas. LLM-driven steering achieves 9.9% higher alignment than keyword matching on semantic agendas (p=0.017), with 13.3% improvement on \textit{Regime Crackdown} specifically (p=0.037), while keyword matching remains competitive on agendas with literal keyword overlap. The coherence cost is minimal: LLM steering reduces coherence by only 2.2% compared to the agenda-agnostic baseline. Counter-agendas that contradict the source material score uniformly low (2.2-2.5) across all methods, confirming that steering cannot fabricate unsupported narratives.

KEditVis: A Visual Analytics System for Knowledge Editing of Large Language Models

arXiv:2603.29689v1 Announce Type: cross Abstract: Large Language Models (LLMs) demonstrate exceptional capabilities in factual question answering, yet they sometimes provide incorrect responses. To address this issue, knowledge editing techniques have emerged as effective methods for correcting factual information in LLMs. However, typical knowledge editing workflows struggle with identifying the optimal set of model layers for editing and rely on summary indicators that provide insufficient guidance. This lack of transparency hinders effective comparison and identification of optimal editing strategies. In this paper, we present KEditVis, a novel visual analytics system designed to assist users in gaining a deeper understanding of knowledge editing through interactive visualizations, improving editing outcomes, and discovering valuable insights for the future development of knowledge editing algorithms. With KEditVis, users can select appropriate layers as the editing target, explore the reasons behind ineffective edits, and perform more targeted and effective edits. Our evaluation, including usage scenarios, expert interviews, and a user study, validates the effectiveness and usability of the system.

Performance Evaluation of LLMs in Automated RDF Knowledge Graph Generation

arXiv:2603.29878v1 Announce Type: cross Abstract: Cloud systems generate large, heterogeneous log data containing critical infrastructure, application, and security information. Transforming these logs into RDF triples enables their integration into knowledge graphs, improving interpretability, root-cause analysis, and cross-service reasoning beyond what raw logs allow. Large Language Models (LLMs) offer a promising approach to automate RDF knowledge graph generation; however, their effectiveness on complex cloud logs remains largely unexplored. In this paper, we evaluate multiple LLM architectures and prompting strategies for automated RDF extraction using a controlled framework with two pipelines for systematically processing semi-structured log data. The extraction pipeline integrates multiple LLMs to identify relevant entities and relationships, automatically generating subject-predicate-object triples. These outputs are evaluated using a dedicated validation pipeline with both syntactic and semantic metrics to assess accuracy, completeness, and quality. Due to the lack of public ground-truth datasets, we created a reference Log-to-KG dataset from OpenStack logs using manual annotation and ontology-driven methods, enabling objective baseline. Our analysis shows that Few-Shot learning is the most effective strategy, with Llama achieving a 99.35% F1 score and 100% valid RDF output while Qwen, NuExtract, and Gemma also perform well under Few-Shot prompting, with Chain-of-Thought approaches maintaining similar accuracy. One-Shot prompting offers a lighter but effective alternative, while Zero-Shot and advanced strategies such as Tree-of-Thought, Self-Critique, and Generate-Multiple perform substantially worse. These results highlight the importance of contextual examples and prompt design for accurate RDF extraction and reveal model-specific limitations across LLM architectures.
❌