❌

Normal view

IDEA2: Expert-in-the-loop competency question elicitation for collaborative ontology engineering

arXiv:2604.01344v1 Announce Type: new Abstract: Competency question (CQ) elicitation represents a critical but resource-intensive bottleneck in ontology engineering. This foundational phase is often hampered by the communication gap between domain experts, who possess the necessary knowledge, and ontology engineers, who formalise it. This paper introduces IDEA2, a novel, semi-automated workflow that integrates Large Language Models (LLMs) within a collaborative, expert-in-the-loop process to address this challenge. The methodology is characterised by a core iterative loop: an initial LLM-based extraction of CQs from requirement documents, a co-creational review and feedback phase by domain experts on an accessible collaborative platform, and an iterative, feedback-driven reformulation of rejected CQs by an LLM until consensus is achieved. To ensure transparency and reproducibility, the entire lifecycle of each CQ is tracked using a provenance model that captures the full lineage of edits, anonymised feedback, and generation parameters. The workflow was validated in 2 real-world scenarios (scientific data, cultural heritage), demonstrating that IDEA2 can accelerate the requirements engineering process, improve the acceptance and relevance of the resulting CQs, and exhibit high usability and effectiveness among domain experts. We release all code and experiments at https://github.com/KE-UniLiv/IDEA2

CRaFT: Circuit-Guided Refusal Feature Selection via Cross-Layer Transcoders

arXiv:2604.01604v1 Announce Type: new Abstract: As safety concerns around large language models (LLMs) grow, understanding the internal mechanisms underlying refusal behavior has become increasingly important. Recent work has studied this behavior by identifying internal features associated with refusal and manipulating them to induce compliance with harmful requests. However, existing refusal feature selection methods rely on how strongly features activate on harmful prompts, which tends to capture superficial signals rather than the causal factors underlying the refusal decision. We propose CRaFT, a circuit-guided refusal feature selection framework that ranks features by their influence on the model's refusal-compliance decision using prompts near the refusal boundary. On Gemma-3-1B-it, CRaFT improves attack success rate (ASR) from 6.7% to 48.2% and outperforms baseline methods across multiple jailbreak benchmarks. These results suggest that circuit influence is a more reliable criterion than activation magnitude for identifying features that causally mediate refusal behavior.

The AnIML Ontology: Enabling Semantic Interoperability for Large-Scale Experimental Data in Interconnected Scientific Labs

arXiv:2604.01728v1 Announce Type: new Abstract: Achieving semantic interoperability across heterogeneous experimental data systems remains a major barrier to data-driven scientific discovery. The Analytical Information Markup Language (AnIML), a flexible XML-based standard for analytical chemistry and biology, is increasingly used in industrial R&D labs for managing and exchanging experimental data. However, the expressivity of the XML schema permits divergent interpretations across stakeholders, introducing inconsistencies that undermine the interoperability the AnIML schema was designed to support. In this paper, we present the AnIML Ontology, an OWL 2 ontology that formalises the semantics of AnIML and aligns it with the Allotrope Data Format to support future cross-system and cross-lab interoperability. The ontology was developed using an expert-in-the-loop approach combining LLM-assisted requirement elicitation with collaborative ontology engineering. We validate the ontology through a multi-layered approach: data-driven transformation of real-world AnIML files into knowledge graphs, competency question verification via SPARQL, and a novel validation protocol based on adversarial negative competency questions mapped to established ontological anti-patterns and enforced via SHACL constraints.

NEMESIS: Noise-suppressed Efficient MAE with Enhanced Superpatch Integration Strategy

arXiv:2604.01612v1 Announce Type: cross Abstract: Volumetric CT imaging is essential for clinical diagnosis, yet annotating 3D volumes is expensive and time-consuming, motivating self-supervised learning (SSL) from unlabeled data. However, applying SSL to 3D CT remains challenging due to the high memory cost of full-volume transformers and the anisotropic spatial structure of CT data, which is not well captured by conventional masking strategies. We propose NEMESIS, a masked autoencoder (MAE) framework that operates on local 128x128x128 superpatches, enabling memory-efficient training while preserving anatomical detail. NEMESIS introduces three key components: (i) noise-enhanced reconstruction as a pretext task, (ii) Masked Anatomical Transformer Blocks (MATB) that perform dual-masking through parallel plane-wise and axis-wise token removal, and (iii) NEMESIS Tokens (NT) for cross-scale context aggregation. On the BTCV multi-organ classification benchmark, NEMESIS with a frozen backbone and a linear classifier achieves a mean AUROC of 0.9633, surpassing fully fine-tuned SuPreM (0.9493) and VoCo (0.9387). Under a low-label regime with only 10% of available annotations, it retains an AUROC of 0.9075, demonstrating strong label efficiency. Furthermore, the superpatch-based design reduces computational cost to 31.0 GFLOPs per forward pass, compared to 985.8 GFLOPs for the full-volume baseline, providing a scalable and robust foundation for 3D medical imaging.

CANDI: Curated Test-Time Adaptation for Multivariate Time-Series Anomaly Detection Under Distribution Shift

arXiv:2604.01845v1 Announce Type: cross Abstract: Multivariate time-series anomaly detection (MTSAD) aims to identify deviations from normality in multivariate time-series and is critical in real-world applications. However, in real-world deployments, distribution shifts are ubiquitous and cause severe performance degradation in pre-trained anomaly detector. Test-time adaptation (TTA) updates a pre-trained model on-the-fly using only unlabeled test data, making it promising for addressing this challenge. In this study, we propose CANDI (Curated test-time adaptation for multivariate time-series ANomaly detection under DIstribution shift), a novel TTA framework that selectively identifies and adapts to potential false positives while preserving pre-trained knowledge. CANDI introduces a False Positive Mining (FPM) strategy to curate adaptation samples based on anomaly scores and latent similarity, and incorporates a plug-and-play Spatiotemporally-Aware Normality Adaptation (SANA) module for structurally informed model updates. Extensive experiments demonstrate that CANDI significantly improves the performance of MTSAD under distribution shift, improving AUROC up to 14% while using fewer adaptation samples.

Mining Instance-Centric Vision-Language Contexts for Human-Object Interaction Detection

arXiv:2604.02071v1 Announce Type: cross Abstract: Human-Object Interaction (HOI) detection aims to localize human-object pairs and classify their interactions from a single image, a task that demands strong visual understanding and nuanced contextual reasoning. Recent approaches have leveraged Vision-Language Models (VLMs) to introduce semantic priors, significantly improving HOI detection performance. However, existing methods often fail to fully capitalize on the diverse contextual cues distributed across the entire scene. To overcome these limitations, we propose the Instance-centric Context Mining Network (InCoM-Net)-a novel framework that effectively integrates rich semantic knowledge extracted from VLMs with instance-specific features produced by an object detector. This design enables deeper interaction reasoning by modeling relationships not only within each detected instance but also across instances and their surrounding scene context. InCoM-Net comprises two core components: Instancecentric Context Refinement (ICR), which separately extracts intra-instance, inter-instance, and global contextual cues from VLM-derived features, and Progressive Context Aggregation (ProCA), which iteratively fuses these multicontext features with instance-level detector features to support high-level HOI reasoning. Extensive experiments on the HICO-DET and V-COCO benchmarks show that InCoM-Net achieves state-of-the-art performance, surpassing previous HOI detection methods. Code is available at https://github.com/nowuss/InCoM-Net.

The Expert Strikes Back: Interpreting Mixture-of-Experts Language Models at Expert Level

arXiv:2604.02178v1 Announce Type: cross Abstract: Mixture-of-Experts (MoE) architectures have become the dominant choice for scaling Large Language Models (LLMs), activating only a subset of parameters per token. While MoE architectures are primarily adopted for computational efficiency, it remains an open question whether their sparsity makes them inherently easier to interpret than dense feed-forward networks (FFNs). We compare MoE experts and dense FFNs using $k$-sparse probing and find that expert neurons are consistently less polysemantic, with the gap widening as routing becomes sparser. This suggests that sparsity pressures both individual neurons and entire experts toward monosemanticity. Leveraging this finding, we zoom out from the neuron to the expert level as a more effective unit of analysis. We validate this approach by automatically interpreting hundreds of experts. This analysis allows us to resolve the debate on specialization: experts are neither broad domain specialists (e.g., biology) nor simple token-level processors. Instead, they function as fine-grained task experts, specializing in linguistic operations or semantic tasks (e.g., closing brackets in LaTeX). Our findings suggest that MoEs are inherently interpretable at the expert level, providing a clearer path toward large-scale model interpretability. Code is available at: https://github.com/jerryy33/MoE_analysis

Neuro-RIT: Neuron-Guided Instruction Tuning for Robust Retrieval-Augmented Language Model

arXiv:2604.02194v1 Announce Type: cross Abstract: Retrieval-Augmented Language Models (RALMs) have demonstrated significant potential in knowledge-intensive tasks; however, they remain vulnerable to performance degradation when presented with irrelevant or noisy retrieved contexts. Existing approaches to enhance robustness typically operate via coarse-grained parameter updates at the layer or module level, often overlooking the inherent neuron-level sparsity of Large Language Models (LLMs). To address this limitation, we propose Neuro-RIT (Neuron-guided Robust Instruction Tuning), a novel framework that shifts the paradigm from dense adaptation to precision-driven neuron alignment. Our method explicitly disentangles neurons that are responsible for processing relevant versus irrelevant contexts using attribution-based neuron mining. Subsequently, we introduce a two-stage instruction tuning strategy that enforces a dual capability for noise robustness: achieving direct noise suppression by functionally deactivating neurons exclusive to irrelevant contexts, while simultaneously optimizing targeted layers for evidence distillation. Extensive experiments across diverse QA benchmarks demonstrate that Neuro-RIT consistently outperforms strong baselines and robustness-enhancing methods.

AutiHero: Engaging Parents in Creating Personalized, Multi-path~Social Narratives for Autistic Children

arXiv:2509.17608v2 Announce Type: replace-cross Abstract: Social narratives help autistic children understand and navigate social situations through stories. To ensure effective practice, however, they often require significant time and effort from parents in customizing the narrative materials and delivering repeated instructions on them. We present AutiHero, a generative AI (GenAI)-based social narrative system, which supports parents to create personalized, multi-path stories targeting specific behavior of their autistic children, while enabling them to explore behavioral choices and causal consequences together in reading. A two-week deployment study with 16 autistic child-parent dyads showed that parents actively created, adapted, and read stories with their children, with increased confidence in everyday behavioral guidance. Our work contributes real-world-contextualized text+image content creation approaches harnessing GenAI, ensuring user-aligned application in sensitive contexts involving autistic children and their parents.

Molmo2: Open Weights and Data for Vision-Language Models with Video Understanding and Grounding

arXiv:2601.10611v4 Announce Type: replace-cross Abstract: Today's strongest video-language models (VLMs) remain proprietary. The strongest open-weight models either rely on synthetic data from proprietary VLMs, effectively distilling from them, or do not disclose their training data or recipe. As a result, the open-source community lacks the foundations needed to improve on the state-of-the-art video (and image) language models. Crucially, many downstream applications require more than just high-level video understanding; they require grounding -- either by pointing or by tracking in pixels. Even proprietary models lack this capability. We present Molmo2, a new family of VLMs that are state-of-the-art among open-source models and demonstrate exceptional new capabilities in point-driven grounding in single image, multi-image, and video tasks. Our key contribution is a collection of 7 new video datasets and 2 multi-image datasets, including a dataset of highly detailed video captions for pre-training, a free-form video Q&A dataset for fine-tuning, a new object tracking dataset with complex queries, and an innovative new video pointing dataset, all collected without the use of closed VLMs. We also present a training recipe for this data utilizing an efficient packing and message-tree encoding scheme, and show bi-directional attention on vision tokens and a novel token-weight strategy improves performance. Our best-in-class 8B model outperforms others in the class of open weight and data models on short videos, counting, and captioning, and is competitive on long-videos. On video-grounding Molmo2 significantly outperforms existing open-weight models like Qwen3-VL (35.5 vs 29.6 accuracy on video counting) and surpasses proprietary models like Gemini 3 Pro on some tasks (38.4 vs 20.0 F1 on video pointing and 56.2 vs 41.1 J&F on video tracking).

An AI-based mental health guardrail and dataset for identifying psychiatric crises in text-based conversations

npj Digital Medicine, Published online: 03 April 2026; doi:10.1038/s41746-026-02579-5

An AI-based mental health guardrail and dataset for identifying psychiatric crises in text-based conversations

The Role of Digital Biomarkers in Physiological Signal-Based Depression Assessment: Systematic Review and Meta-Analysis

Background: Digital biomarkers are increasingly being used to support depression assessment by providing objective, continuous, and real-time physiological and behavioral data. However, most existing studies have focused on individual biomarkers, such as sleep or cardiac parameters, while integrative evaluations that capture the multidimensional nature of depression remain limited. Objective: This systematic review evaluated digital biomarkers for depression and synthesized evidence on differences between individuals with depression and controls. Methods: Eligible studies included observational or interventional studies examining digital biomarkers for depression with validated outcome measures. We searched major international and Korean databases, including MEDLINE, PsycINFO, CINAHL, IEEE Xplore, Web of Science, Cochrane Library, KISS, RISS, KMbase, and KoreaMed, from inception to December 28, 2025. Risk of bias was assessed using the Quality Assessment of Diagnostic Accuracy Studies-2 tool and the Scottish Intercollegiate Guidelines Network checklist. Meta-analyses were conducted using random-effects models with the Hartung-Knapp-Sidik-Jonkman method, and other outcomes were narratively summarized. Results: The search yielded 39,617 records, of which 132 studies involving 57,852 participants met the inclusion criteria. These studies encompassed various digital biomarkers, including sleep, physical activity, cardiac measures, smartphone-derived data, speech, GPS data, and circadian rhythms. A meta-analysis of 22 studies (6947 participants) revealed that individuals with depression had significantly longer sleep onset latency (5 studies; n=292; +4.75 min, 95% CI 2.46-7.04; =.005; 95% prediction interval [PI] 0.01-10.27) and time in bed (3 studies; n=236; +31.81 min, 95% CI 18.22-45.39; =.01; 95% PI 2.28-55.16). Physical activity counts were also significantly lower (5 studies; n=462; standardized mean difference −0.71, 95% CI −1.33 to −0.09; =.03; 95% PI −2.18 to 0.71). Although individuals with depression showed a lower sleep efficiency, higher mean heart rate, and lower SD of normal-to-normal intervals, these differences were not statistically significant. Other digital markers yielded inconsistent results. Overall, these findings indicate that no single digital biomarker sufficiently captures depression-related changes. Instead, the results support the superiority of personalized, multimodal approaches. However, the generalizability of these findings is limited by the lack of standardized data collection protocols and high clinical heterogeneity across studies, as reflected in wide PIs. Conclusions: Certain digital biomarkers, particularly sleep onset latency and physical activity counts, showed consistent average differences between the depression and control groups. However, wide PIs indicate substantial variability across settings, suggesting that no single marker is sufficient for reliable detection. This study advances the field by providing a comprehensive meta-analysis of multidimensional digital biomarkers, establishing a quantitative foundation for objective depression screening and monitoring. These findings support the use of personalized, multimodal digital phenotyping approaches and highlight the need for standardized, clinically interpretable frameworks for real-world depression monitoring. Trial Registration: PROSPERO CRD42024518136; https://www.crd.york.ac.uk/PROSPERO/view/CRD42024518136

Github Integrates AI to Improve Accessibility Issue Management and Automate Feedback Triage

2 April 2026 at 22:45

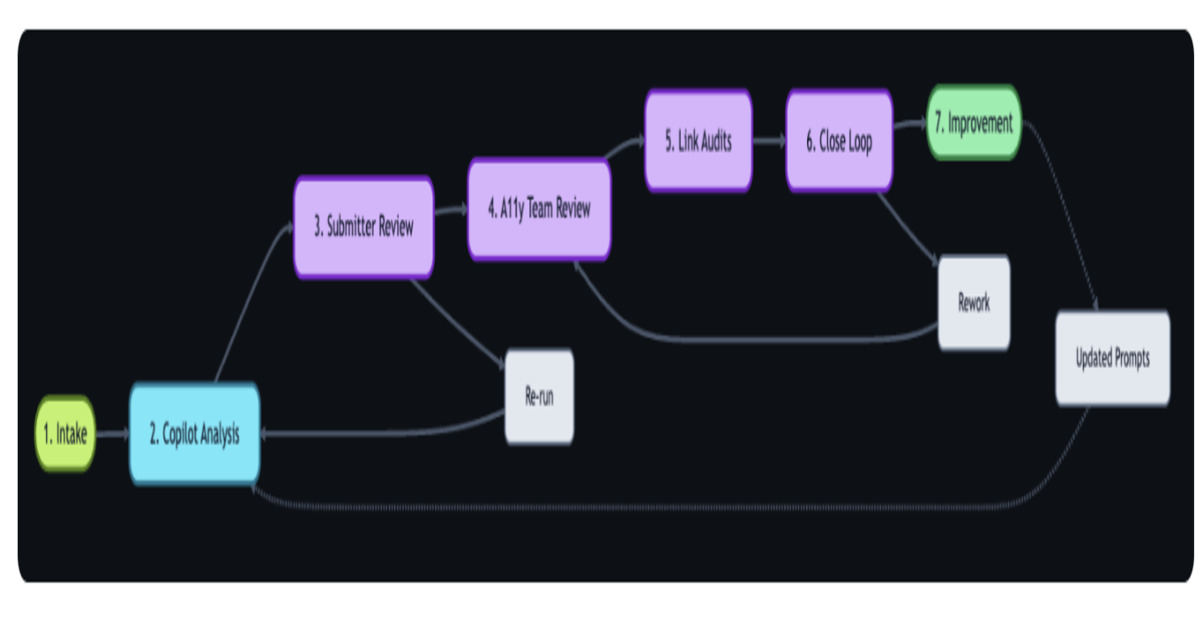
GitHub has launched a continuous AI-powered workflow to manage accessibility feedback at scale. Using GitHub Actions, Copilot, and Models APIs, the system centralizes reports, analyzes WCAG compliance, and automates triage while maintaining human validation. Teams now resolve feedback faster, improving inclusion and cross-functional collaboration.

By Leela Kumili

A robust vision language model for molecular status prediction and radiology report generation in adult-type diffuse gliomas

npj Digital Medicine, Published online: 02 April 2026; doi:10.1038/s41746-026-02581-x

A robust vision language model for molecular status prediction and radiology report generation in adult-type diffuse gliomas

Cell-type-specific transposon demethylation and TAD remodeling in aging mouse brain

A multi-omic single-cell atlas of the aging mouse brain reveals cell-type-specific transposon methylation changes, strengthening of 3D genome boundaries, and regionally heterogeneous aging signatures. These findings offer a resource to understand the molecular mechanisms of brain aging and guide future research on neurodegeneration.
  • ✇cs.AI, q-bio.NC updates on arXiv.org
  • SimMOF: AI agent for Automated MOF Simulations Jaewoong Lee · Taeun Bae · Jihan Kim
    arXiv:2603.29152v1 Announce Type: new Abstract: Metal-organic frameworks (MOFs) offer a vast design space, and as such, computational simulations play a critical role in predicting their structural and physicochemical properties. However, MOF simulations remain difficult to access because reliable analysis require expert decisions for workflow construction, parameter selection, tool interoperability, and the preparation of computational ready structures. Here, we introduce SimMOF, a large langu
     

SimMOF: AI agent for Automated MOF Simulations

arXiv:2603.29152v1 Announce Type: new Abstract: Metal-organic frameworks (MOFs) offer a vast design space, and as such, computational simulations play a critical role in predicting their structural and physicochemical properties. However, MOF simulations remain difficult to access because reliable analysis require expert decisions for workflow construction, parameter selection, tool interoperability, and the preparation of computational ready structures. Here, we introduce SimMOF, a large language model based multi agent framework that automates end-to-end MOF simulation workflows from natural language queries. SimMOF translates user requests into dependency aware plans, generates runnable inputs, orchestrates multiple agents to execute simulations, and summarizes results with analysis aligned to the user query. Through representative case studies, we show that SimMOF enables adaptive and cognitively autonomous workflows that reflect the iterative and decision driven behavior of human researchers and as such provides a scalable foundation for data driven MOF research.

AI in Work-Based Learning: Understanding the Purposes and Effects of Intelligent Tools Among Student Interns

arXiv:2603.28786v1 Announce Type: cross Abstract: This study examined how student interns in Philippine higher education use intelligent tools during their OJT. Data were collected from 384 respondents using a structured questionnaire that asked about AI tool usage, task-specific applications, and perceptions of confidence, ethics, and support. Analysis of task-based usage identified four main purposes: productivity and report writing, communication and content drafting, technical assistance and code support, and independent task completion. ChatGPT was the most commonly used AI tool, followed by Quillbot, Canva AI, and Grammarly. Students reported moderate confidence in using AI and applied these tools selectively and ethically during OJT tasks. This indicate that AI tools assist student interns in various OJT activities related to work-readiness. The study suggests that higher education programs include AI literacy and onboarding. Clear policies and fair access to AI tools are important to support responsible use and prepare students for future careers.

CIPHER: Counterfeit Image Pattern High-level Examination via Representation

arXiv:2603.29356v1 Announce Type: cross Abstract: The rapid progress of generative adversarial networks (GANs) and diffusion models has enabled the creation of synthetic faces that are increasingly difficult to distinguish from real images. This progress, however, has also amplified the risks of misinformation, fraud, and identity abuse, underscoring the urgent need for detectors that remain robust across diverse generative models. In this work, we introduce Counterfeit Image Pattern High-level Examination via Representation(CIPHER), a deepfake detection framework that systematically reuses and fine-tunes discriminators originally trained for image generation. By extracting scale-adaptive features from ProGAN discriminators and temporal-consistency features from diffusion models, CIPHER captures generation-agnostic artifacts that conventional detectors often overlook. Through extensive experiments across nine state-of-the-art generative models, CIPHER demonstrates superior cross-model detection performance, achieving up to 74.33% F1-score and outperforming existing ViT-based detectors by over 30% in F1-score on average. Notably, our approach maintains robust performance on challenging datasets where baseline methods fail, with up to 88% F1-score on CIFAKE compared to near-zero performance from conventional detectors. These results validate the effectiveness of discriminator reuse and cross-model fine-tuning, establishing CIPHER as a promising approach toward building more generalizable and robust deepfake detection systems in an era of rapidly evolving generative technologies.

NeoNet: An End-to-End 3D MRI-Based Deep Learning Framework for Non-Invasive Prediction of Perineural Invasion via Generation-Driven Classification

arXiv:2603.29449v1 Announce Type: cross Abstract: Minimizing invasive diagnostic procedures to reduce the risk of patient injury and infection is a central goal in medical imaging. And yet, noninvasive diagnosis of perineural invasion (PNI), a critical prognostic factor involving infiltration of tumor cells along the surrounding nerve, still remains challenging, due to the lack of clear and consistent imaging criteria criteria for identifying PNI. To address this challenge, we present NeoNet, an integrated end-to-end 3D deep learning framework for PNI prediction in cholangiocarcinoma that does not rely on predefined image features. NeoNet integrates three modules: (1) NeoSeg, utilizing a Tumor-Localized ROI Crop (TLCR) algorithm; (2) NeoGen, a 3D Latent Diffusion Model (LDM) with ControlNet, conditioned on anatomical masks to generate synthetic image patches, specifically balancing the dataset to a 1:1 ratio; and (3) NeoCls, the final prediction module. For NeoCls, we developed the PNI-Attention Network (PattenNet), which uses the frozen LDM encoder and specialized 3D Dual Attention Blocks (DAB) designed to detect subtle intensity variations and spatial patterns indicative of PNI. In 5-fold cross-validation, NeoNet outperformed baseline 3D models and achieved the highest performance with a maximum AUC of 0.7903.
❌