❌

Reading view

Uber’s Hive Federation Decentralizes 16K Datasets and 10+ PB for Zero-Downtime Analytics at Scale
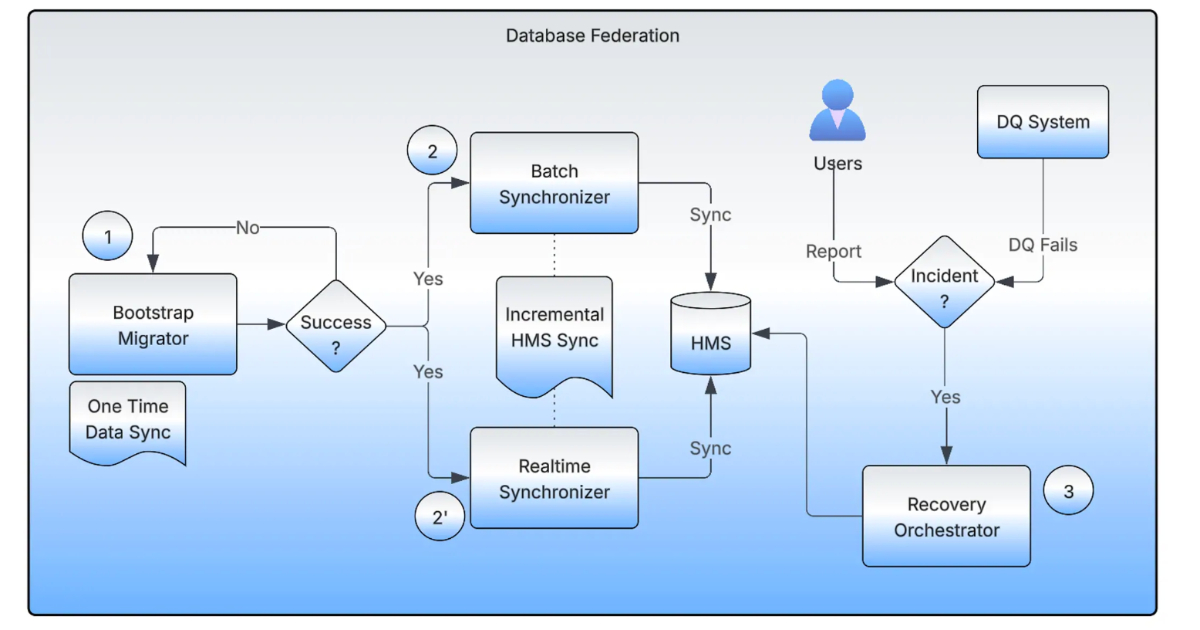
Uber has decentralized its Hive data warehouse, migrating 16,000 datasets totaling over 10 petabytes using pointer-based federation. The migration ensures zero downtime, strict ACL enforcement, improved governance, and scalable, domain-specific datasets for analytics and machine learning workloads.

By Leela Kumili
  •  

Pinterest Reduces Spark OOM Failures by 96% Through Auto Memory Retries

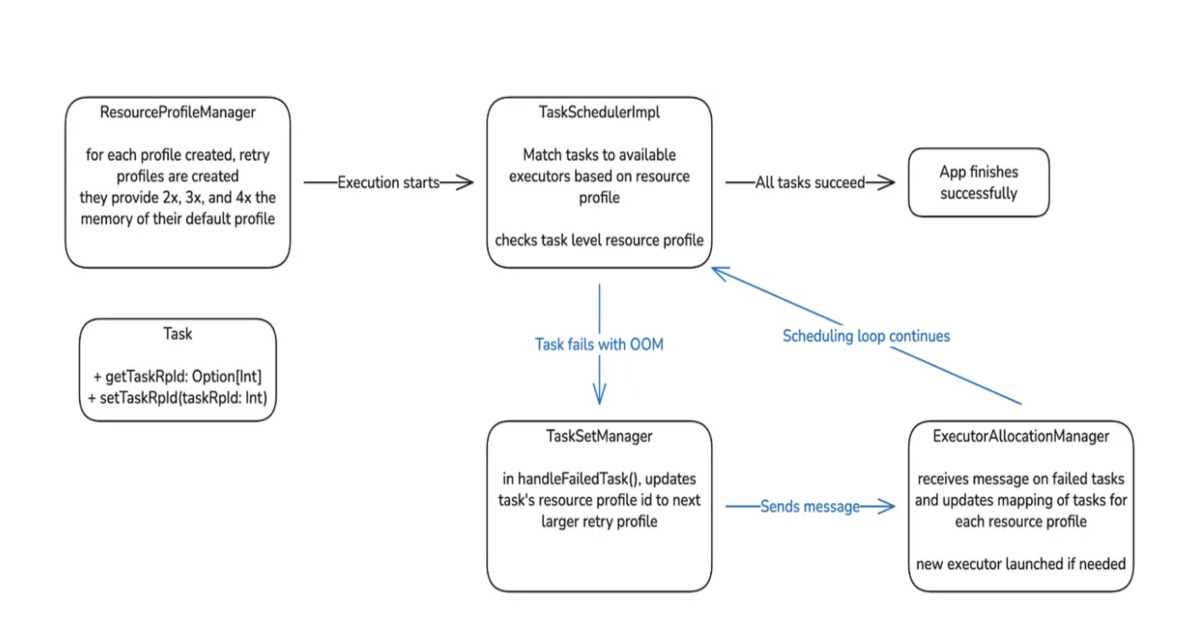
Pinterest Engineering cut Apache Spark out-of-memory failures by 96% using improved observability, configuration tuning, and automatic memory retries. Staged rollout, dashboards, and proactive memory adjustments stabilized data pipelines, reduced manual intervention, and lowered operational overhead across tens of thousands of daily jobs.

By Leela Kumili
  •  
❌