❌

Reading view

The Download: glass chips and “AI-free” logos

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology.

Future AI chips could be built on glass 

Human-made glass is thousands of years old. But it’s now poised to find its way into the AI chips used in the world’s newest and largest data centers.  

This year, a South Korean company called Absolics will start producing special glass panels that make next-generation computing hardware more powerful and efficient. Other companies, including Intel, are also pushing forward in this area.  

If all goes well, the technology could reduce the energy demands of chips in AI data centers—and even consumer laptops and mobile devices. Read the full story. 

—Jeremy Hsu

The must-reads 

I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 

1 The race is on to establish a globally recognized “AI-free” logo 
Organizations are rushing to develop a universal label for human-made products. (BBC) 
+ A “QuitGPT” campaign is urging people to ditch ChatGPT. (MIT Technology Review) 

2 Elizabeth Warren wants answers on xAI’s access to military data 
The Pentagon reportedly gave it access to classified networks. (NBC News) 
+ Here’s how chatbots could be used for targeting decisions. (MIT Technology Review) 
+ The DoD is struggling to upgrade software for fighter jets. (Bloomberg $) 

3 Models are applying to be the faces of AI romance scams 
The “AI face models” are duping victims out of their money. (Wired $) 
+ Survivors have revealed how the “pig butchering” scams work. (MIT Technology Review) 

4 Meta is planning layoffs that could affect over 20% of staff 
The job cuts could offset its costly bet on AI. (Reuters $) 
+ There’s a long history of fears about AI’s impact on jobs. (MIT Technology Review) 

5 ByteDance delayed launching a video AI model after copyright disputes 
It famously generated footage of Tom Cruise and Brad Pitt fighting. (The Information $) 

6 Cybersecurity investigators have exposed a huge North Korean con 
The scammers secured remote jobs in the US, then stole money and sensitive information. (NBC News) 

7 A Chinese AI startup is set for a whopping $18 billion valuation 
That’s more than quadruple its valuation just three months ago. (Bloomberg $) 
+ Chinese open models are spreading fast—here’s why that matters. (MIT Technology Review)  

8 Peter Thiel has started a lecture series about the antichrist in Rome 
His plans have drawn attention from the Catholic Church. (Reuters $) 

9 Norway is fighting back against internet enshittification 
It’s joined a global campaign against the online world’s decay. (The Guardian) 
+ We may need to move beyond the big platforms. (MIT Technology Review) 

10 How a startup plans to resurrect the dodo 
Humans wiped them out nearly 400 years ago—can gene editing bring them back now? (Guardian) 

Quote of the day 

“I would build fission weapons. I would build fusion weapons. Nuclear weapons have been one of the most stabilizing forces in history—ever.” 

—Anduril founder Palmer Luckey shares his love of nukes with Axios. 

One More Thing 
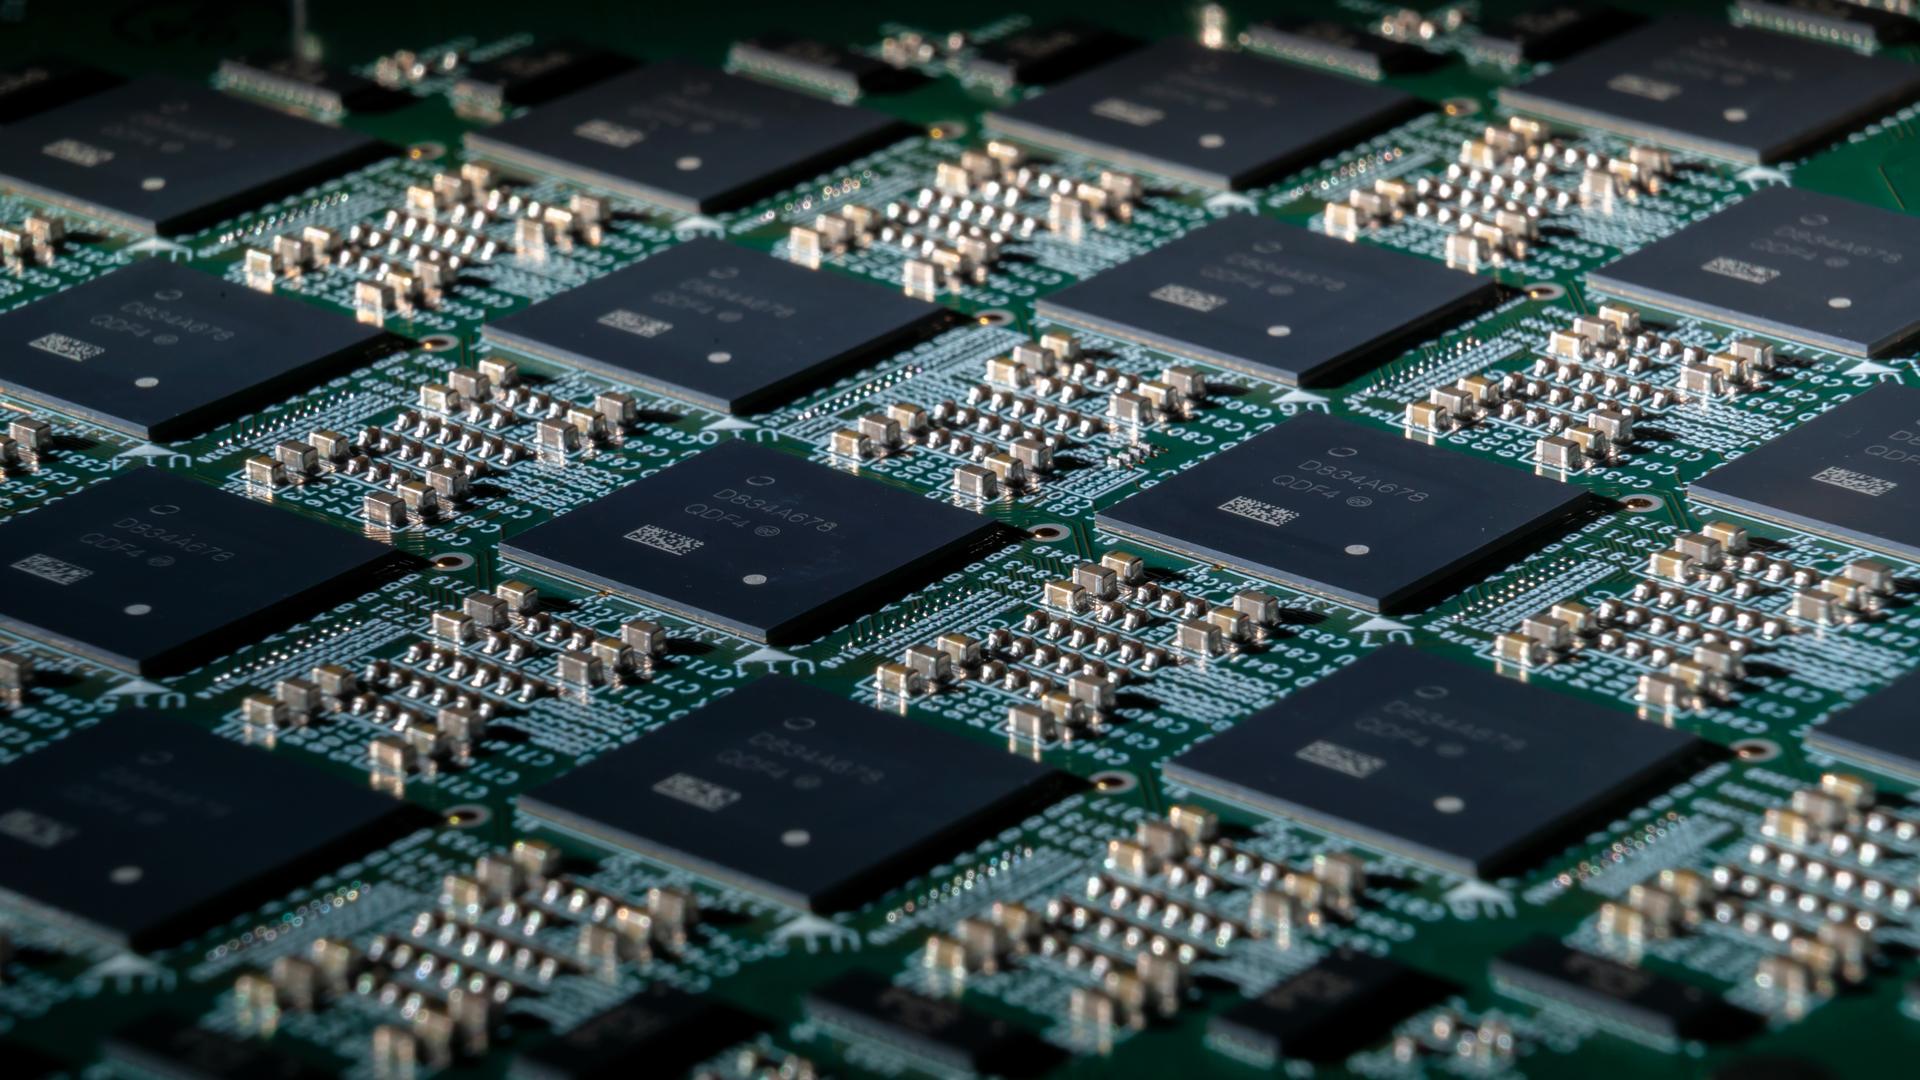
We need a moonshot for computing 

grid of chips
TIM HERMAN/INTEL

The US government is organizing itself for the next era of computing. Ultimately, it has one big choice to make: adopt a conservative strategy that aims to preserve its lead for the next five years—or orient itself toward genuine computing moonshots. 

There is no shortage of candidates, including quantum computing, neuromorphic computing and reversible computing. And there are plenty of novel materials and devices. These possibilities could even be combined to form hybrid computing systems. 

The National Semiconductor Technology Center can drive these ideas forward. To be successful, it would do well to follow DARPA’s lead by focusing on moonshot programs. Read the full story. 
 
—Brady Helwig & PJ Maykish 

We can still have nice things 

A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.) 
 
+ A UPS delivery driver heroically escaped from two murderous turkeys. 
+ Art’s love affair with cats is charmingly depicted in a new book. 
+ The humble pea and six other forgotten superfoods promise accessible nutritional power. 
+ MF DOOM: Long Island to Leeds is the Transatlantic tale of your favorite rapper’s favorite rapper. 

  •  

Tumor-informed liquid biopsy detection of structural variants in high grade serous ovarian cancer

Oncoscience. 2026 Mar 5;13:44-54. doi: 10.18632/oncoscience.645. eCollection 2026.

ABSTRACT

BACKGROUND: High grade serous ovarian cancer (HGSOC) recurs frequently and commercial tests have emerged for tumor-informed, cell-free DNA (cfDNA)-based detection of minimal residual disease. These tests are based on somatic single nucleotide variants prevalent in many cancers and thus are not well matched to HGSOC, which is dominated by structural genomic rearrangements. The purpose of this study was to evaluate the feasibility of a structural-variant (SV)-informed, cfDNA-based method for detecting clonal and subclonal HGSOC disease burden.

METHODS: A method was developed for detecting patient-specific SV breakpoints using digital droplet PCR (ddPCR) with custom tumor-informed primer/probe pairs. Test parameters were first estimated using synthetic cfDNA generated by ultrasonication of genomic DNA from ovarian cancer cell lines. The optimized workflow was implemented in which whole genome sequencing of multisite pre-treatment HGSOC biopsies performed and high confidence SVs were called by multiple published SV callers. Real-time PCR and ddPCR were used for assay development.

RESULTS: Following the optimized workflow, tumor-specific SV breakpoint-spanning primers/probe sets of four HGSOC patients' multisite biopsies were designed and validated by real-time PCR and ddPCR. Together with four HGSOCs, a total of 29 SVs breakpoints-spanning tumor-informed primers/probe sets were designed and validated in multisite biopsies. 15 validated tumor-specific SVs were selected for quantification in their corresponding liquid biopsies using the validated ddPCR, and 9 had measurements in liquid biopsies.

CONCLUSIONS: Our result shows the detection of SVs from pre-treatment cfDNA using tumor-informed breakpoints-spanning ddPCR is feasible and may enable a novel and sensitive method for monitoring on-treatment disease burden.

PMID:41835357 | PMC:PMC12981705 | DOI:10.18632/oncoscience.645

  •  

The DIME Architecture: A Unified Operational Algorithm for Neural Representation, Dynamics, Control and Integration

arXiv:2603.12286v1 Announce Type: new Abstract: Modern neuroscience has accumulated extensive evidence on perception, memory, prediction, valuation, and consciousness, yet still lacks an explicit operational architecture capable of integrating these phenomena within a unified computational framework. Existing theories address specific aspects of neural function: predictive coding and active inference emphasize hierarchical inference and prediction error minimization; engram theories explain memory through distributed cell assemblies; neuromodulatory accounts focus on value-dependent regulation of plasticity and behaviour; and global workspace or large-scale network models investigate mechanisms underlying conscious access. Despite their explanatory power, these approaches remain only partially integrated at the architectural level. This work introduces DIME (Detect-Integrate-Mark-Execute), a neural architecture organizing perception, memory, valuation, and conscious access within a common operational cycle. The framework includes four interacting components: engrams, distributed recurrent neural structures supporting multiple activation trajectories; execution threads, spatiotemporal trajectories implementing neural processes; marker systems, neuromodulatory and limbic mechanisms regulating gain, plasticity, and trajectory selection; and hyperengrams, large-scale integrative states associated with operational conscious access. The framework is consistent with empirical evidence from hippocampal indexing, recurrent cortical processing, replay phenomena, large-scale network integration, and neuromodulatory regulation. Formulated at an abstract computational level, DIME may also inform artificial intelligence and robotics by providing an architectural template in which representation, valuation, and temporal sequencing emerge from a unified mechanism. An extended theoretical exposition is available in a companion monograph on Zenodo.
  •  

Formation of Artificial Neural Assemblies by Biologically Plausible Inhibition Mechanisms

arXiv:2603.12416v1 Announce Type: new Abstract: As proposed by Hebb's theory, neural assemblies are groups of excitatory neurons that fire synchronously and exhibit high synaptic density, representing external stimuli and supporting cognitive functions such as language and decision-making. Recently, a model called Assembly Calculus (AC) was proposed, enabling the formation of artificial neural assemblies through the $k$-winners-take-all selection process and Hebbian learning. Although the model is capable of forming assemblies according to Hebb's theory, the adopted selection process does not incorporate essential aspects of biological neural computation, as neural activity, which is often governed by statistical distributions consistent with power-law scaling. Given this limitation, the present work aimed to bring the model's dynamics closer to that observed in real cortical networks. To achieve this, a new selection mechanism inspired by the dynamics of gamma oscillation cycles, called E%-winners-take-all, was implemented, combined with an inhibition process based on the ratio between excitatory and inhibitory neurons observed in various regions of the cerebral cortex. The results obtained from our model (called E%-WTA model) were compared with those of the original model, and the analyses demonstrated that the introduced modifications allowed the network's own dynamics to determine the size of the formed assemblies. Furthermore, the recovery rate of these groups, through the evocation of the stimuli that generated them, became superior to that obtained in the original model.
  •  

ToolTree: Efficient LLM Agent Tool Planning via Dual-Feedback Monte Carlo Tree Search and Bidirectional Pruning

arXiv:2603.12740v1 Announce Type: new Abstract: Large Language Model (LLM) agents are increasingly applied to complex, multi-step tasks that require interaction with diverse external tools across various domains. However, current LLM agent tool planning methods typically rely on greedy, reactive tool selection strategies that lack foresight and fail to account for inter-tool dependencies. In this paper, we present ToolTree, a novel Monte Carlo tree search-inspired planning paradigm for tool planning. ToolTree explores possible tool usage trajectories using a dual-stage LLM evaluation and bidirectional pruning mechanism that enables the agent to make informed, adaptive decisions over extended tool-use sequences while pruning less promising branches before and after the tool execution. Empirical evaluations across both open-set and closed-set tool planning tasks on 4 benchmarks demonstrate that ToolTree consistently improves performance while keeping the highest efficiency, achieving an average gain of around 10\% compared to the state-of-the-art planning paradigm.
  •  

Context is all you need: Towards autonomous model-based process design using agentic AI in flowsheet simulations

arXiv:2603.12813v1 Announce Type: new Abstract: Agentic AI systems integrating large language models (LLMs) with reasoning and tooluse capabilities are transforming various domains - in particular, software development. In contrast, their application in chemical process flowsheet modelling remains largely unexplored. In this work, we present an agentic AI framework that delivers assistance in an industrial flowsheet simulation environment. To this end, we show the capabilities of GitHub Copilot (GitHub, Inc., 2026), when using state-of-the-art LLMs, such as Claude Opus 4.6 (Anthropic, PBC, 2026), to generate valid syntax for our in-house process modelling tool Chemasim using the technical documentation and a few commented examples as context. Based on this, we develop a multi-agent system that decomposes process development tasks with one agent solving the abstract problem using engineering knowledge and another agent implementing the solution as Chemasim code. We demonstrate the effectiveness of our framework for typical flowsheet modelling examples, including (i) a reaction/separation process, (ii) a pressure-swing distillation, and (iii) a heteroazeotropic distillation including entrainer selection. Along these lines, we discuss current limitations of the framework and outline future research directions to further enhance its capabilities.
  •  

Semantic Invariance in Agentic AI

arXiv:2603.13173v1 Announce Type: new Abstract: Large Language Models (LLMs) increasingly serve as autonomous reasoning agents in decision support, scientific problem-solving, and multi-agent coordination systems. However, deploying LLM agents in consequential applications requires assurance that their reasoning remains stable under semantically equivalent input variations, a property we term semantic invariance.Standard benchmark evaluations, which assess accuracy on fixed, canonical problem formulations, fail to capture this critical reliability dimension. To address this shortcoming, in this paper we present a metamorphic testing framework for systematically assessing the robustness of LLM reasoning agents, applying eight semantic-preserving transformations (identity, paraphrase, fact reordering, expansion, contraction, academic context, business context, and contrastive formulation) across seven foundation models spanning four distinct architectural families: Hermes (70B, 405B), Qwen3 (30B-A3B, 235B-A22B), DeepSeek-R1, and gpt-oss (20B, 120B). Our evaluation encompasses 19 multi-step reasoning problems across eight scientific domains. The results reveal that model scale does not predict robustness: the smaller Qwen3-30B-A3B achieves the highest stability (79.6% invariant responses, semantic similarity 0.91), while larger models exhibit greater fragility.
  •  

Optimizing Task Completion Time Updates Using POMDPs

arXiv:2603.12340v1 Announce Type: cross Abstract: Managing announced task completion times is a fundamental control problem in project management. While extensive research exists on estimating task durations and task scheduling, the problem of when and how to update completion times communicated to stakeholders remains understudied. Organizations must balance announcement accuracy against the costs of frequent timeline updates, which can erode stakeholder trust and trigger costly replanning. Despite the prevalence of this problem, current approaches rely on static predictions or ad-hoc policies that fail to account for the sequential nature of announcement management. In this paper, we formulate the task announcement problem as a Partially Observable Markov Decision Process (POMDP) where the control policy must decide when to update announced completion times based on noisy observations of true task completion. Since most state variables (current time and previous announcements) are fully observable, we leverage the Mixed Observability MDP (MOMDP) framework to enable more efficient policy optimization. Our reward structure captures the dual costs of announcement errors and update frequency, enabling synthesis of optimal announcement control policies. Using off-the-shelf solvers, we generate policies that act as feedback controllers, adaptively managing announcements based on belief state evolution. Simulation results demonstrate significant improvements in both accuracy and announcement stability compared to baseline strategies, achieving up to 75\% reduction in unnecessary updates while maintaining or improving prediction accuracy.
  •  

Shattering the Shortcut: A Topology-Regularized Benchmark for Multi-hop Medical Reasoning in LLMs

arXiv:2603.12458v1 Announce Type: cross Abstract: While Large Language Models (LLMs) achieve expert-level performance on standard medical benchmarks through single-hop factual recall, they severely struggle with the complex, multi-hop diagnostic reasoning required in real-world clinical settings. A primary obstacle is "shortcut learning", where models exploit highly connected, generic hub nodes (e.g., "inflammation") in knowledge graphs to bypass authentic micro-pathological cascades. To address this, we introduce ShatterMed-QA, a bilingual benchmark of 10,558 multi-hop clinical questions designed to rigorously evaluate deep diagnostic reasoning. Our framework constructs a topology-regularized medical Knowledge Graph using a novel $k$-Shattering algorithm, which physically prunes generic hubs to explicitly sever logical shortcuts. We synthesize the evaluation vignettes by applying implicit bridge entity masking and topology-driven hard negative sampling, forcing models to navigate biologically plausible distractors without relying on superficial elimination. Comprehensive evaluations of 21 LLMs reveal massive performance degradation on our multi-hop tasks, particularly among domain-specific models. Crucially, restoring the masked evidence via Retrieval-Augmented Generation (RAG) triggers near-universal performance recovery, validating ShatterMed-QA's structural fidelity and proving its efficacy in diagnosing the fundamental reasoning deficits of current medical AI. Explore the dataset, interactive examples, and full leaderboards at our project website: https://shattermed-qa-web.vercel.app/
  •  

TRACE: Temporal Rule-Anchored Chain-of-Evidence on Knowledge Graphs for Interpretable Stock Movement Prediction

arXiv:2603.12500v1 Announce Type: cross Abstract: We present a Temporal Rule-Anchored Chain-of-Evidence (TRACE) on knowledge graphs for interpretable stock movement prediction that unifies symbolic relational priors, dynamic graph exploration, and LLM-guided decision making in a single end-to-end pipeline. The approach performs rule-guided multi-hop exploration restricted to admissible relation sequences, grounds candidate reasoning chains in contemporaneous news, and aggregates fully grounded evidence into auditable \texttt{UP}/\texttt{DOWN} verdicts with human-readable paths connecting text and structure. On an S\&P~500 benchmark, the method achieves 55.1\% accuracy, 55.7\% precision, 71.5\% recall, and 60.8\% F1, surpassing strong baselines and improving recall and F1 over the best graph baseline under identical evaluation. The gains stem from (i) rule-guided exploration that focuses search on economically meaningful motifs rather than arbitrary walks, and (ii) text-grounded consolidation that selectively aggregates high-confidence, fully grounded hypotheses instead of uniformly pooling weak signals. Together, these choices yield higher sensitivity without sacrificing selectivity, delivering predictive lift with faithful, auditably interpretable explanations.
  •  

ELLA: Generative AI-Powered Social Robots for Early Language Development at Home

arXiv:2603.12508v1 Announce Type: cross Abstract: Early language development shapes children's later literacy and learning, yet many families have limited access to scalable, high-quality support at home. Recent advances in generative AI make it possible for social robots to move beyond scripted interactions and engage children in adaptive, conversational activities, but it remains unclear how to design such systems for pre-schoolers and how children engage with them over time in the home. We present ELLA (Early Language Learning Agent), an autonomous, generative AI-powered social robot that supports early language development through interactive storytelling, parent-selected language targets, and scaffolded dialogue. Using a multi-phased, human-centered process, we interviewed parents (n=7) and educators (n=5) and iteratively refined ELLA through twelve in-home design workshops. We then deployed ELLA with ten children for eight days. We report design insights from in-home workshops, characterize children's engagement and behaviors during deployment, and distill design implications for generative AI-powered social robots supporting early language learning at home.
  •  

CALF: Communication-Aware Learning Framework for Distributed Reinforcement Learning

arXiv:2603.12543v1 Announce Type: cross Abstract: Distributed reinforcement learning policies face network delays, jitter, and packet loss when deployed across edge devices and cloud servers. Standard RL training assumes zero-latency interaction, causing severe performance degradation under realistic network conditions. We introduce CALF (Communication-Aware Learning Framework), which trains policies under realistic network models during simulation. Systematic experiments demonstrate that network-aware training substantially reduces deployment performance gaps compared to network-agnostic baselines. Distributed policy deployments across heterogeneous hardware validate that explicitly modelling communication constraints during training enables robust real-world execution. These findings establish network conditions as a major axis of sim-to-real transfer for Wi-Fi-like distributed deployments, complementing physics and visual domain randomisation.
  •  

Multiscale Structure-Guided Latent Diffusion for Multimodal MRI Translation

arXiv:2603.12581v1 Announce Type: cross Abstract: Although diffusion models have achieved remarkable progress in multi-modal magnetic resonance imaging (MRI) translation tasks, existing methods still tend to suffer from anatomical inconsistencies or degraded texture details when handling arbitrary missing-modality scenarios. To address these issues, we propose a latent diffusion-based multi-modal MRI translation framework, termed MSG-LDM. By leveraging the available modalities, the proposed method infers complete structural information, which preserves reliable boundary details. Specifically, we introduce a style--structure disentanglement mechanism in the latent space, which explicitly separates modality-specific style features from shared structural representations, and jointly models low-frequency anatomical layouts and high-frequency boundary details in a multi-scale feature space. During the structure disentanglement stage, high-frequency structural information is explicitly incorporated to enhance feature representations, guiding the model to focus on fine-grained structural cues while learning modality-invariant low-frequency anatomical representations. Furthermore, to reduce interference from modality-specific styles and improve the stability of structure representations, we design a style consistency loss and a structure-aware loss. Extensive experiments on the BraTS2020 and WMH datasets demonstrate that the proposed method outperforms existing MRI synthesis approaches, particularly in reconstructing complete structures. The source code is publicly available at https://github.com/ziyi-start/MSG-LDM.
  •  

Feynman: Knowledge-Infused Diagramming Agent for Scalable Visual Designs

arXiv:2603.12597v1 Announce Type: cross Abstract: Visual design is an essential application of state-of-the-art multi-modal AI systems. Improving these systems requires high-quality vision-language data at scale. Despite the abundance of internet image and text data, knowledge-rich and well-aligned image-text pairs are rare. In this paper, we present a scalable diagram generation pipeline built with our agent, Feynman. To create diagrams, Feynman first enumerates domain-specific knowledge components (''ideas'') and performs code planning based on the ideas. Given the plan, Feynman translates ideas into simple declarative programs and iterates to receives feedback and visually refine diagrams. Finally, the declarative programs are rendered by the Penrose diagramming system. The optimization-based rendering of Penrose preserves the visual semantics while injecting fresh randomness into the layout, thereby producing diagrams with visual consistency and diversity. As a result, Feynman can author diagrams along with grounded captions with very little cost and time. Using Feynman, we synthesized a dataset with more than 100k well-aligned diagram-caption pairs. We also curate a visual-language benchmark, Diagramma, from freshly generated data. Diagramma can be used for evaluating the visual reasoning capabilities of vision-language models. We plan to release the dataset, benchmark, and the full agent pipeline as an open-source project.
  •  

Seeing Eye to Eye: Enabling Cognitive Alignment Through Shared First-Person Perspective in Human-AI Collaboration

arXiv:2603.12701v1 Announce Type: cross Abstract: Despite advances in multimodal AI, current vision-based assistants often remain inefficient in collaborative tasks. We identify two key gulfs: a communication gulf, where users must translate rich parallel intentions into verbal commands due to the channel mismatch , and an understanding gulf, where AI struggles to interpret subtle embodied cues. To address these, we propose Eye2Eye, a framework that leverages first-person perspective as a channel for human-AI cognitive alignment. It integrates three components: (1) joint attention coordination for fluid focus alignment, (2) revisable memory to maintain evolving common ground, and (3) reflective feedback allowing users to clarify and refine AI's understanding. We implement this framework in an AR prototype and evaluate it through a user study and a post-hoc pipeline evaluation. Results show that Eye2Eye significantly reduces task completion time and interaction load while increasing trust, demonstrating its components work in concert to improve collaboration.
  •  

Team LEYA in 10th ABAW Competition: Multimodal Ambivalence/Hesitancy Recognition Approach

arXiv:2603.12848v1 Announce Type: cross Abstract: Ambivalence/hesitancy recognition in unconstrained videos is a challenging problem due to the subtle, multimodal, and context-dependent nature of this behavioral state. In this paper, a multimodal approach for video-level ambivalence/hesitancy recognition is presented for the 10th ABAW Competition. The proposed approach integrates four complementary modalities: scene, face, audio, and text. Scene dynamics are captured with a VideoMAE-based model, facial information is encoded through emotional frame-level embeddings aggregated by statistical pooling, acoustic representations are extracted with EmotionWav2Vec2.0 and processed by a Mamba-based temporal encoder, and linguistic cues are modeled using fine-tuned transformer-based text models. The resulting unimodal embeddings are further combined using multimodal fusion models, including prototype-augmented variants. Experiments on the BAH corpus demonstrate clear gains of multimodal fusion over all unimodal baselines. The best unimodal configuration achieved an average MF1 of 70.02%, whereas the best multimodal fusion model reached 83.25%. The highest final test performance, 71.43%, was obtained by an ensemble of five prototype-augmented fusion models. The obtained results highlight the importance of complementary multimodal cues and robust fusion strategies for ambivalence/hesitancy recognition.
  •  
❌