❌

Normal view

  • βœ‡InfoQ
  • Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs Leela Kumili
    Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually. By Leela Kumili
     

Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs

7 September 2026 at 22:06

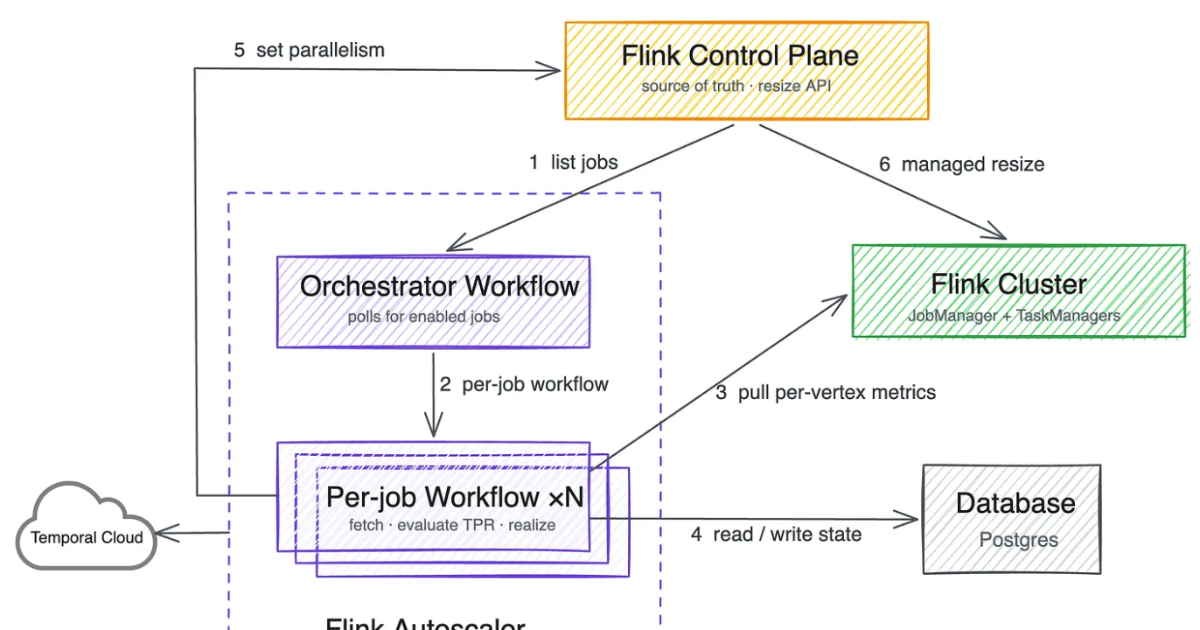
Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually.

By Leela Kumili
Uber’s Hive Federation Decentralizes 16K Datasets and 10+ PB for Zero-Downtime Analytics at Scale

9 April 2026 at 21:54

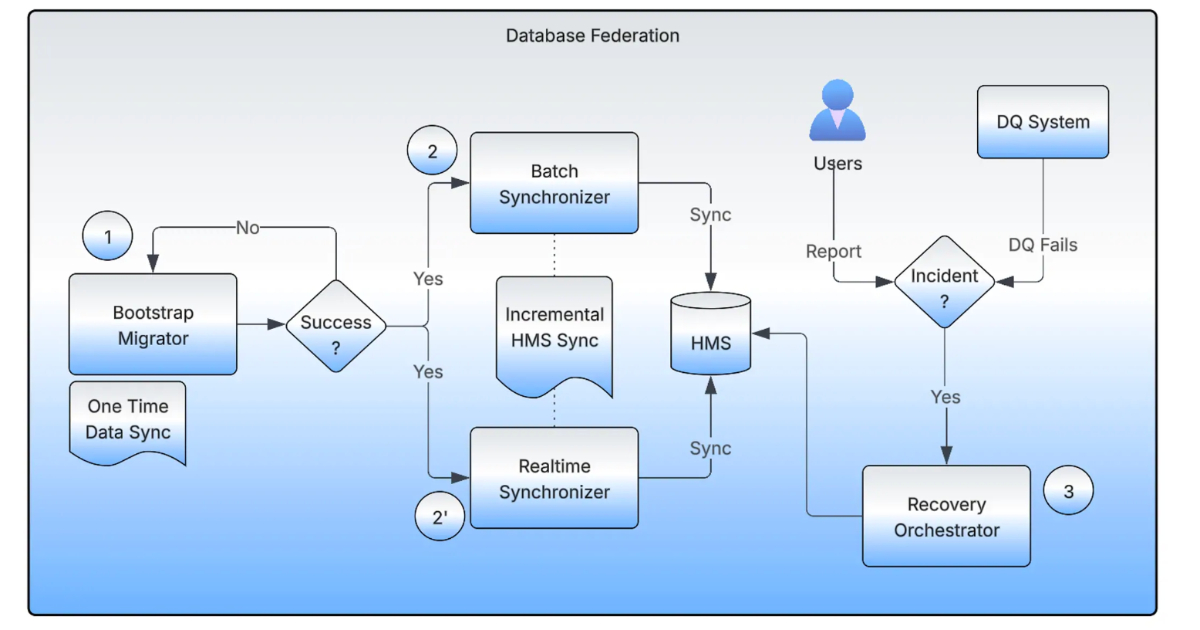
Uber has decentralized its Hive data warehouse, migrating 16,000 datasets totaling over 10 petabytes using pointer-based federation. The migration ensures zero downtime, strict ACL enforcement, improved governance, and scalable, domain-specific datasets for analytics and machine learning workloads.

By Leela Kumili
  • βœ‡InfoQ
  • Pinterest Reduces Spark OOM Failures by 96% Through Auto Memory Retries Leela Kumili
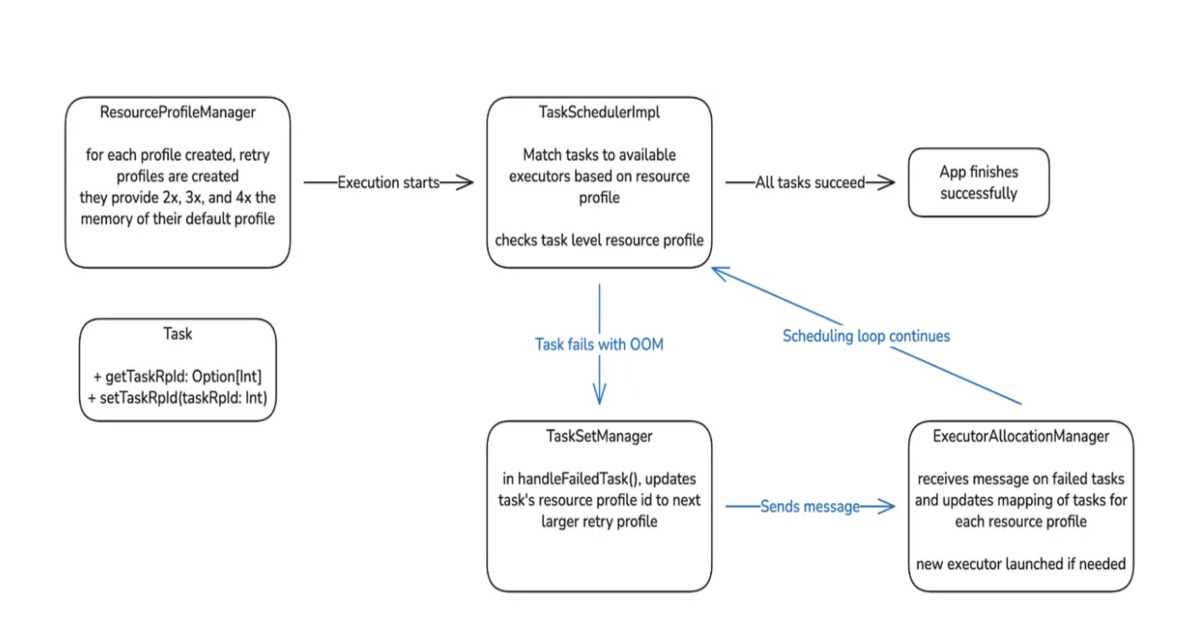
    Pinterest Engineering cut Apache Spark out-of-memory failures by 96% using improved observability, configuration tuning, and automatic memory retries. Staged rollout, dashboards, and proactive memory adjustments stabilized data pipelines, reduced manual intervention, and lowered operational overhead across tens of thousands of daily jobs. By Leela Kumili
     

Pinterest Reduces Spark OOM Failures by 96% Through Auto Memory Retries

6 April 2026 at 22:32

Pinterest Engineering cut Apache Spark out-of-memory failures by 96% using improved observability, configuration tuning, and automatic memory retries. Staged rollout, dashboards, and proactive memory adjustments stabilized data pipelines, reduced manual intervention, and lowered operational overhead across tens of thousands of daily jobs.

By Leela Kumili

Anthropic Designs Three-Agent Harness Supports Long-Running Full-Stack AI Development

4 April 2026 at 22:24

Anthropic introduces a three-agent harness separating planning, generation, and evaluation to improve long-running autonomous AI workflows for frontend and full-stack development. Industry commentary highlights structured approaches, iterative evaluation, and practical methods to maintain coherence and quality over multi-hour AI coding sessions.

By Leela Kumili

Github Integrates AI to Improve Accessibility Issue Management and Automate Feedback Triage

2 April 2026 at 22:45

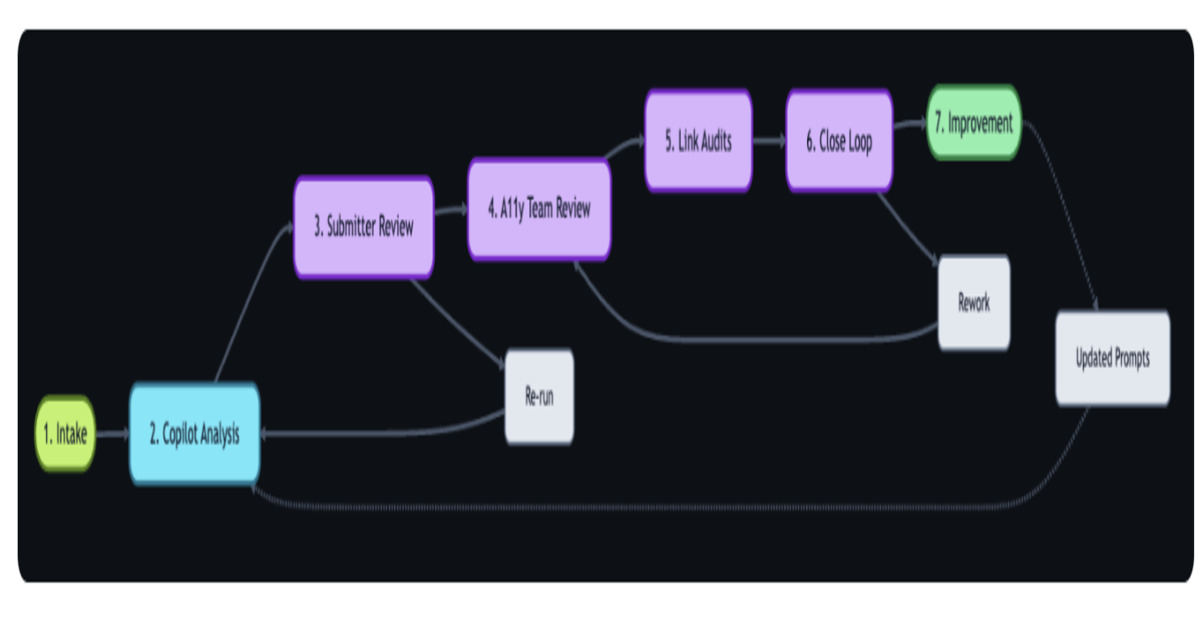
GitHub has launched a continuous AI-powered workflow to manage accessibility feedback at scale. Using GitHub Actions, Copilot, and Models APIs, the system centralizes reports, analyzes WCAG compliance, and automates triage while maintaining human validation. Teams now resolve feedback faster, improving inclusion and cross-functional collaboration.

By Leela Kumili
❌