❌

Normal view

Lyft Moves Streaming Fleet to Apache Flink Kubernetes Operator

16 September 2026 at 19:00

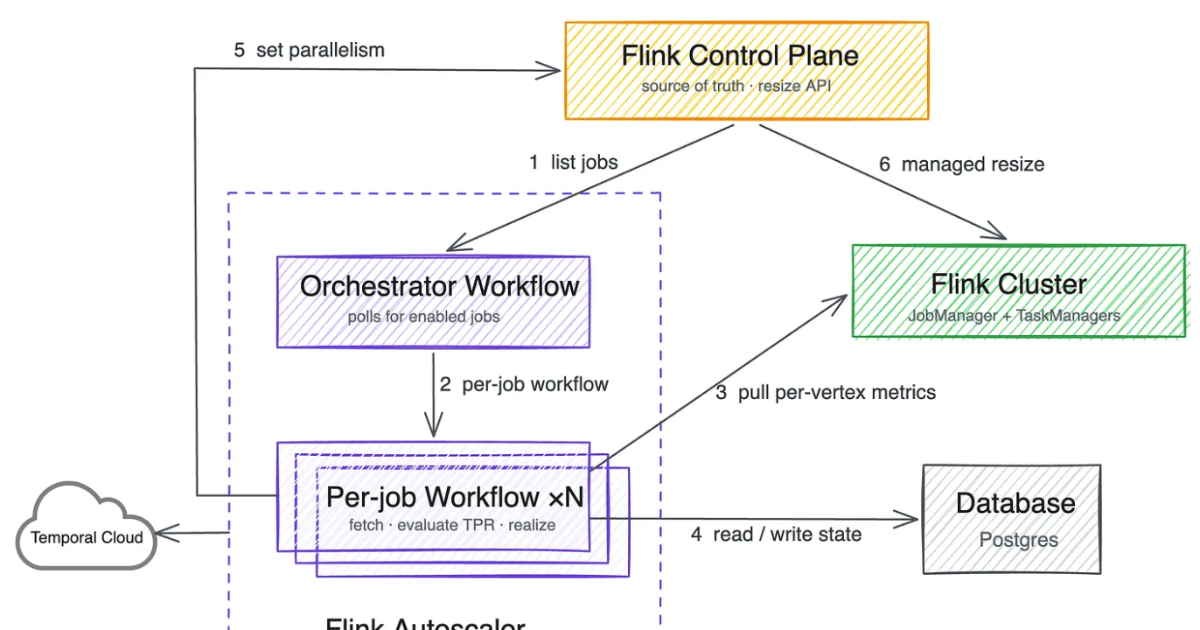
Lyft has moved hundreds of production Flink jobs from a 2020 in-house Kubernetes operator to the Apache Flink Kubernetes Operator, unlocking last-state upgrades, in-place autoscaling and resource autotuning across the fleet.

By Mark Silvester
  • βœ‡InfoQ
  • Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs Leela Kumili
    Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually. By Leela Kumili
     

Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs

7 September 2026 at 22:06

Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually.

By Leela Kumili
  • βœ‡InfoQ
  • Article: The Schema Proliferation Problem in Kafka and Flink Pipelines: How to Solve It Spoorthi Basu
    Schema proliferation builds slowly and gets expensive fast. One schema per event type feels right until there are ten tables, union queries spanning all of them, and a single field rename touching every schema. Discriminator-based schema consolidation collapses that to two tables, turning multi-table unions into a single query, while new variants are additive and don't break existing consumers. By Spoorthi Basu
     

Article: The Schema Proliferation Problem in Kafka and Flink Pipelines: How to Solve It

25 May 2026 at 21:00

Schema proliferation builds slowly and gets expensive fast. One schema per event type feels right until there are ten tables, union queries spanning all of them, and a single field rename touching every schema. Discriminator-based schema consolidation collapses that to two tables, turning multi-table unions into a single query, while new variants are additive and don't break existing consumers.

By Spoorthi Basu
❌