❌

Reading view

Netflix Reworks Conductor for 420 Million Monthly Workflow Executions and 10X Larger Workflows

Netflix has reworked its Conductor workflow orchestration engine to handle larger workloads, increasing supported workflow size from about 2,500 to 30,000 tasks and reducing p99 workflow evaluation latency by about 40%. Conductor 4.0 separates workflow metadata from task data, moves evaluation to asynchronous processing, and introduces dynamic worker allocation and concurrency controls.

By Leela Kumili
  •  

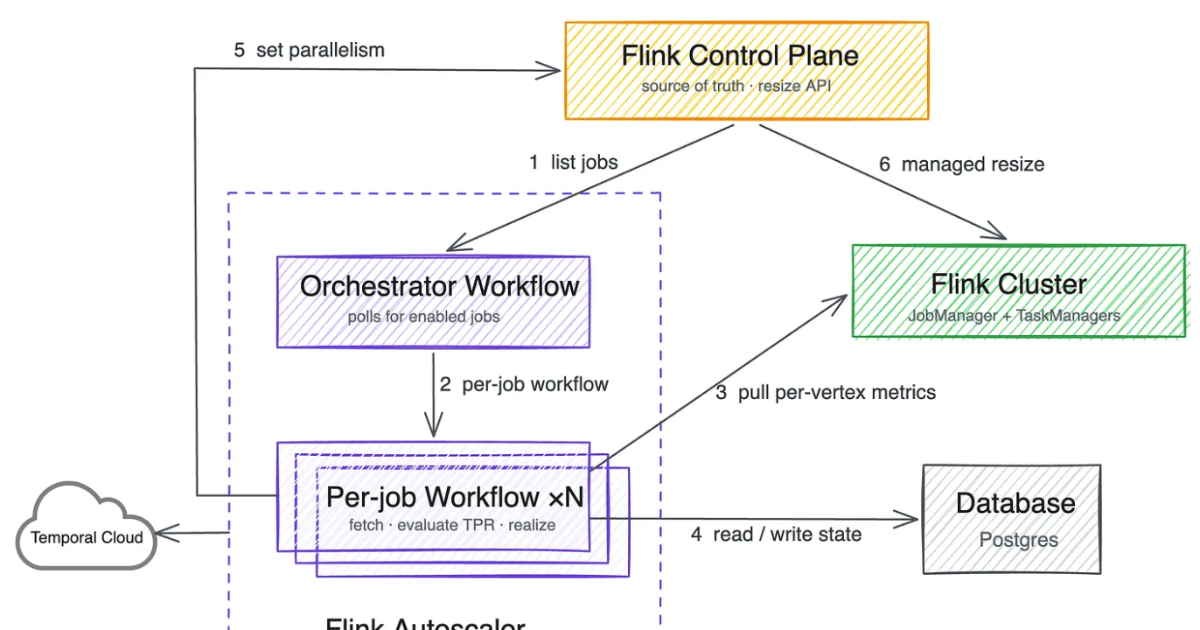
Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs

Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually.

By Leela Kumili
  •  

Article: Architecting Cloud-Native Kafka: From Tiered Storage Towards a Diskless Future

This article explores Kafka's transition toward a cloud-native architecture, examining how tiered storage, FinOps telemetry, elastic consumer scaling, virtual clusters, and Share Groups reshape the operational and economic model of event streaming platforms. It also analyzes emerging diskless-storage proposals and their architectural trade-offs.

By Viquar Khan
  •  

Java News Roundup: WildFly, Micronaut, Spring AI, Apache Fory, GlassFish Plugin, Open Liberty

This week's Java roundup for May 18th, 2026, features news highlighting: GA releases of WildFly 40, Micronaut 5.0, Maven Embedded GlassFish Plugin 8.0 and Apache Fory 1.0; the May 2026 edition of Open Liberty; point releases of Gatherers4j, Apache and Kafka; and the seventh milestone release of Spring AI 2.0.

By Michael Redlich
  •  

Article: The Schema Proliferation Problem in Kafka and Flink Pipelines: How to Solve It

Schema proliferation builds slowly and gets expensive fast. One schema per event type feels right until there are ten tables, union queries spanning all of them, and a single field rename touching every schema. Discriminator-based schema consolidation collapses that to two tables, turning multi-table unions into a single query, while new variants are additive and don't break existing consumers.

By Spoorthi Basu
  •  
❌