❌

Normal view

Presentation: Fixing the AI Infra Scale Problem by Stuffing 1M Sandboxes in a Single Server

9 September 2026 at 19:00

Felipe Huici explains how Unikraft achieves millisecond cold boots, stateful scale-to-zero, and extreme density for sandboxing AI workloads. He discusses isolation primitives, Linux kernel optimizations, and snapshotting tricks, demonstrating how to maintain sub-10ms performance at scale while integrating seamlessly into Kubernetes environments with hardware-level security.

By Felipe Huici
  • βœ‡InfoQ
  • Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs Leela Kumili
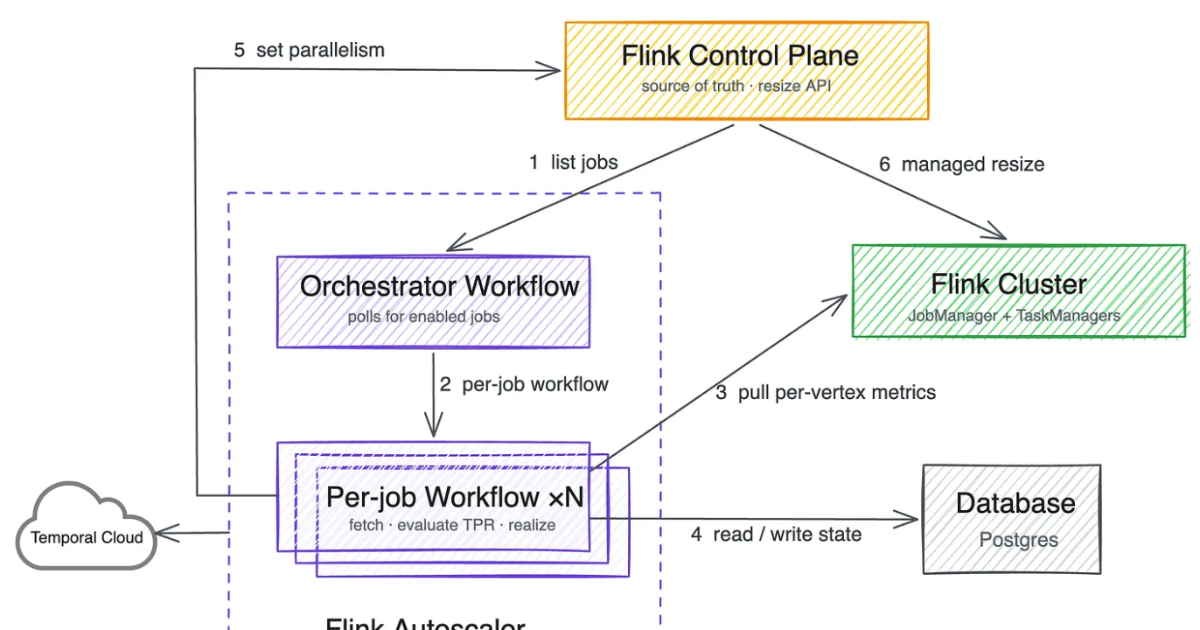
    Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually. By Leela Kumili
     

Netflix Moves toward Open Source Flink Autoscaler for 30,000+ Streaming Jobs

7 September 2026 at 22:06

Netflix is moving toward the open-source Apache Flink Autoscaler for more than 30,000 streaming jobs across multiple AWS regions. The operator-level approach addresses limitations of Netflix’s cluster level autoscaler for complex, stateful pipelines. Netflix reports a 58% reduction in annualized Flink compute expenditure for one team, saving approximately $1.1 million annually.

By Leela Kumili
  • βœ‡InfoQ
  • Presentation: Realtime and Batch Processing of GPU Workloads Joseph Stein
    Joseph Stein discusses engineering an enterprise AI-as-a-Service platform within a private cloud data center. He explains how to maximize underutilized GPU pools via multi-namespace scheduling, leverage Valkey and Lua for atomic priority queuing and backpressure management, mitigate OWASP Top 10 LLM risks via central proxy gateways, and scale batch pipelines using a custom S3-to-Kafka proxy. By Joseph Stein
     

Presentation: Realtime and Batch Processing of GPU Workloads

26 May 2026 at 17:08

Joseph Stein discusses engineering an enterprise AI-as-a-Service platform within a private cloud data center. He explains how to maximize underutilized GPU pools via multi-namespace scheduling, leverage Valkey and Lua for atomic priority queuing and backpressure management, mitigate OWASP Top 10 LLM risks via central proxy gateways, and scale batch pipelines using a custom S3-to-Kafka proxy.

By Joseph Stein

Article: Bloom Filters: Theory, Engineering Trade‑offs, and Implementation in Go

7 April 2026 at 17:00

This article walks you through the Go implementation of Bloom filters to optimize the performance of a recommender. It cover the architectural view, Bloom filter mechanics, Go integration, parameter tuning, and practical lessons learned from making it work under production constraints.

By Gabor Koos
❌