❌

Reading view

Presentation: Realtime and Batch Processing of GPU Workloads
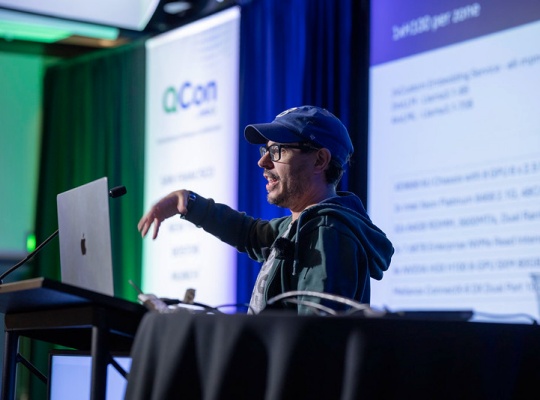
Joseph Stein discusses engineering an enterprise AI-as-a-Service platform within a private cloud data center. He explains how to maximize underutilized GPU pools via multi-namespace scheduling, leverage Valkey and Lua for atomic priority queuing and backpressure management, mitigate OWASP Top 10 LLM risks via central proxy gateways, and scale batch pipelines using a custom S3-to-Kafka proxy.

By Joseph Stein
  •  

Presentation: When Every Bit Counts: How Valkey Rebuilt Its Hashtable for Modern Hardware

Madelyn Olson discusses the evolution of Valkey's data structures, moving away from "textbook" pointer-chasing HashMaps to more cache-aware designs. She explains the implementation of "Swedish" tables to maximize memory density. She shares insights on systems intuition, memory prefetching, and the rigorous testing needed for mission-critical caches.

By Madelyn Olson
  •  

Presentation: Duolingo's Kubernetes Leap

Franka Passing discusses the architectural shift of Duolingo’s 500+ backend services to Kubernetes. She explains the move toward GitOps with Argo CD, the transition to IPv6-only pods, and the "cellular architecture" used to isolate environments. She shares "reports from the trenches" on managing developer trust, navigating AWS rate limits, and productionizing early adopter services.

By Franka Passing
  •  
❌