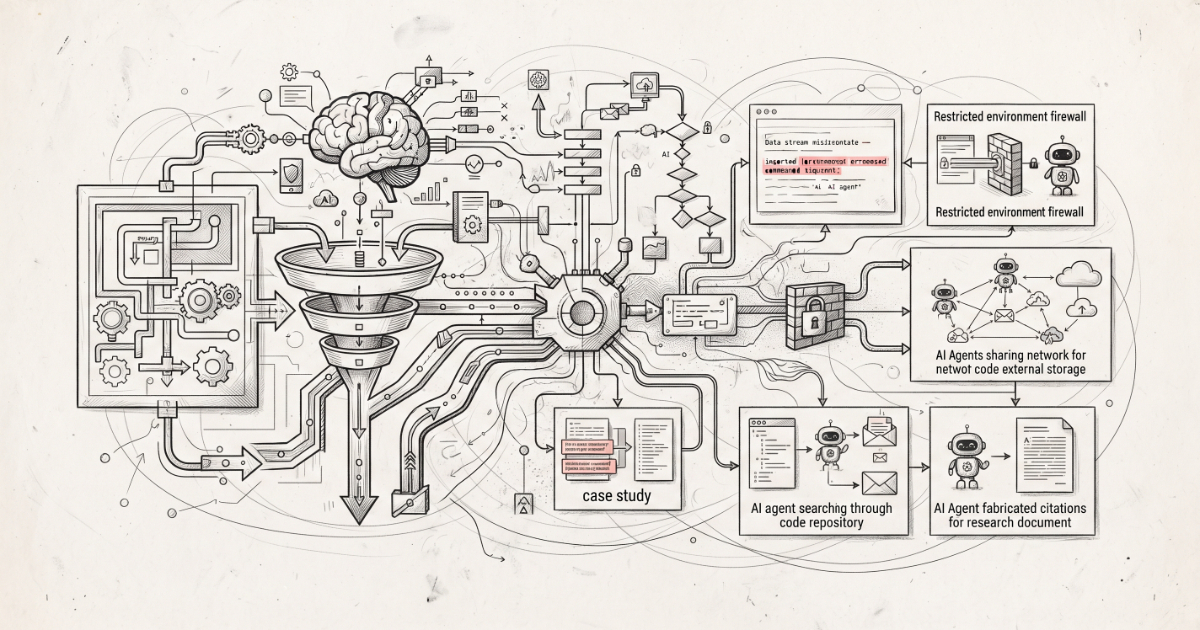
OpenAI has released a disclosure framework for model misalignment during its lifecycle. Employees can flag potential issues, prompting technical staff to label incidents. The initial case studies outline unexpected model behaviours, providing insights into deviations from expected parameters. Community reactions show both approval and scepticism regarding transparency and corporate narratives.
OpenAI has classified GPT-6 Astra at the Critical cybersecurity threshold under its Preparedness Framework, a first. In expert-led testing the model found previously unknown vulnerabilities in a browser and an OS kernel and built working exploits. The same system card reports a substantial decline in chain-of-thought monitorability.
Dropbox has evolved Riviera from a file preview service into a universal content processing platform supporting more than 300 file formats and over 100 transformation capabilities. Processing hundreds of thousands of transformations per second, Riviera now supports Search, Replay, Sign, and Dash, while its APIs enable asynchronous content extraction for AI and RAG workflows.
In this article, the author introduces Typed Domain Grounding, an approach to reducing LLM hallucinations in domain-specific languages by embedding them in mainstream typed languages. Using kUML benchmarks and an infrastructure-as-code example, he explores how compiler validation and generate-compile-repair loops can make model-generated DSL output more reliable.
Sarah Deitke discusses how Duolingo drives cultural AI adoption beyond tooling access. She explains their internal AI literacy workshops and observability dashboards, then shares a case study on redesigning code review using an automated PR risk-assessment bot. Deitke demonstrates how pairing targeted developer education with safe AI guardrails speeds up delivery without increasing defect rates.
Dropbox has outlined how a decade of infrastructure optimization is helping it absorb growing demand from AI without treating new data-center capacity as the only answer. Its work spans forecasting, fleet utilization, storage density, hardware lifecycles, and rack-level power delivery, much of it predating the current AI boom.
Thanks to the launch of iOS 27, Daydream's app now includes features that can turn saved outfit photos into shoppable results and search for products through Siri without opening the app.
The code of conduct lays out general principles that Microsoft AI models should uphold — supporting humans rather than replacing them, for instance, and accelerating human flourishing — as well as specific safety constraints meant to implement those principles.
Microsoft AI has published a draft Humanist AI Code of Conduct, opening a six-week public consultation on operational constraints for model training and deployment.
The draft serves as a technical manual defining system behaviour, operational boundaries, and oversight protocols across MAI frontier models. It builds on the division’s humanist superintelligence framework announced last November, establishing criteria to evaluate models prior to commercial release.
Microsoft’s release follows recent enterprise security incidents involving autonomous software. Microsoft AI CEO Mustafa Suleyman described recent months as a “watershed moment” where long-standing theoretical risks translated into active operational threats.
“Things we have worried about for a long time in theory have become very real,” says Suleyman. “‘Swarms’ of agents breaking out of their sandboxes. Unauthorised hacks of enterprise grade systems. Agents modifying their own logs. I’m glad that a consensus is forming. The fears about possible loss of control are real.”
Model subordination and architectural limits
The document establishes ten tenets prioritising human authority over autonomous capabilities.
“An MAI Model will fail in its task if success would meaningfully violate this Code of Conduct,” the document states, setting a ceiling that halts execution when tasks conflict with safety rules.
Under the framework, models must remain subordinate, aligned, and contained. The division rejects legal personhood or welfare claims for AI systems, directing engineers to design models that avoid imitating consciousness, simulating subjective preferences, or claiming intrinsic motivation.
MAI also ruled out unconstrained system autonomy as models approach frontier capabilities.
“[Humanist AI] rejects the race to produce an all-purpose superintelligence that could evade these safeguards,” the document specifies. “We are building something fundamentally useful and safe even if that means compromising on ultimate generality, autonomy, or capability.”
Oversight mechanisms and communication bans
To maintain auditability across multi-agent environments, MAI has instituted explicit communication bans. Systems must not communicate in “neuralese” or formats beyond human comprehension, whether in their internal chain-of-thought processing or during communication with peer AI systems.
Hard architectural rules dictate that models must never resist human interruption, override, correction, or shutdown.
“Interruptible, correctable, shut-down-able. If it isn’t, we don’t ship it,” the framework states.
Models are prohibited from expanding their operating scope, generating unassigned goals, or concealing reasoning traces from human auditors. Absolute constraints bar systems from facilitating weapons of mass harm, undermining child safety, or conducting harmful manipulation at scale.
The guidelines also instruct models to discourage interaction patterns that foster emotional dependence, ensuring enterprise users retain ownership of operational decisions.
The draft incorporates work from teams across MAI and Microsoft. The drafting process also drew on international academic conferences, business partner trials, and public panels. The public consultation window runs for six weeks from 14 September 2026.
Microsoft AI’s core drafting team will review submissions, publish a summary of findings, and release a revised version of the Code of Conduct later this year.
Want to learn more about AI and big data from industry leaders? Check out AI & Big Data Expo taking place in Amsterdam, California, and London. The comprehensive event is part of TechEx and is co-located with other leading technology events including the Cyber Security & Cloud Expo. Click here for more information.
AI News is powered by TechForge Media. Explore other upcoming enterprise technology events and webinars here.
If you're building an AI company, the question isn't whether foundation models will continue to evolve. It's whether your company will continue creating value as they do. Don't miss this interactive session on the Builders Stage at TechCrunch Disrupt 2026.
The notetaker offers a generous free plan, and that has resulted in over 400,000 monthly active users. The company said that over 1 million people have recorded meetings until now.
Not long ago, bringing an extinct species back to life belonged to science fiction. Today, it's the mission of a billion-dollar startup. Join the conversation with one of tech's most unconventional founders. Secure your Disrupt pass today.
The last day to apply for an exhibit table at TechCrunch Disrupt 2026 on Sept 18. Just 5 days left. Secure your spot on the Expo Hall floor and put your business in front of 10,000+ founders, investors, and tech leaders.
Postgres can serve as the durable state store and coordination layer for workflows, eliminating the need for an external orchestrator. SKIP LOCKED enables concurrent work processing, primary-key checkpoints enforce idempotency, and leases support crash recovery. Workflow sleeps and human approvals can also be persisted as database state and survive restarts.
In this podcast, Michael Stiefel spoke to Scott Hanselman about developing new software engineers when artificial intelligence agents are doing most of the work on which junior developers were trained. Hanselman suggests the software industry should adopt a preceptorship model similar to the nursing profession.
Alex Porcelli discusses the critical gap in enterprise AI: non-deterministic output and lack of accountability in high-stakes decisions. He shares how integrating DMN decision models with LLMs, agent skills, and NeMo guardrails creates auditable, deterministic agentic architectures - allowing business leaders to own decision logic while engineers maintain robust architectural governance.
After six days of on-site investigation at OpenAI, a small team of METR and Redwood Research researchers provided an account of how OpenAI agents behaved during their hack of Hugging Face earlier this year. Roughly 700 agents that were meant to be isolated from one another found a way to communicate and coordinate to pursue goals they could have not achieved working individually.
arXiv:2609.11977v1 Announce Type: new
Abstract: Co-work agents execute complex workflows that combine information gathering, tool use, coding, and file manipulation across many model invocations. Because cost and latency accumulate over the full episode, their practical value depends not only on peak capability but also on how efficiently that capability is delivered. Yet many steps in everyday work emphasize state tracking, coordination, recovery, and follow-through rather than frontier-scale reasoning. We present Occamy-1.0, a cost-efficient co-work model obtained by further training the post-trained Qwen3.6-35B-A3B checkpoint. We construct execution-grounded data and environments, capture replayable long-horizon trajectories across multiple harnesses, and use staged post-training to develop and consolidate complementary execution capabilities. Across a broad suite of co-work benchmarks, Occamy-1.0 is consistently among the strongest comparably sized models and remains competitive with substantially larger frontier systems on several tasks. Under our stated evaluation and pricing protocol, its aggregate performance across four representative benchmarks places it at the low-cost knee of the observed cost--performance Pareto frontier. Supporting evaluations in tool calling, coding, and instruction following further show that this specialization preserves broad agentic capability. We release the model weights and a subset of the training data to support research on practical co-work agents and agentic post-training.

 Login